Minkuk Kim

Minkuk Kim

Ph.D. student in Artificial Intelligence · Kyung Hee University

NowVisiting researcher at UIUC, Prof. James M. Rehg's lab, working closely with Dr. Junho Kim · Sept 2026 – Mar 2027

About

I am a Ph.D. student in Artificial Intelligence at Kyung Hee University, advised by Prof. Seong-Tae Kim in the AugMented Intelligence (AMI) Laboratory. My research focuses on video-language understanding, with a particular interest in long-form and streaming videos that involve extended temporal contexts.

A central theme of my work is memory-augmented video understanding: how models can retain, structure, and retrieve visual evidence over long temporal contexts. I study this problem through dense video captioning and video question answering, where models need to localize relevant events and reason over temporally distributed information.

Looking ahead, I hope to extend video understanding toward more realistic and interactive settings, such as egocentric video and embodied/VLA scenarios, where perception can eventually support action.

News

Publications

Google Scholar
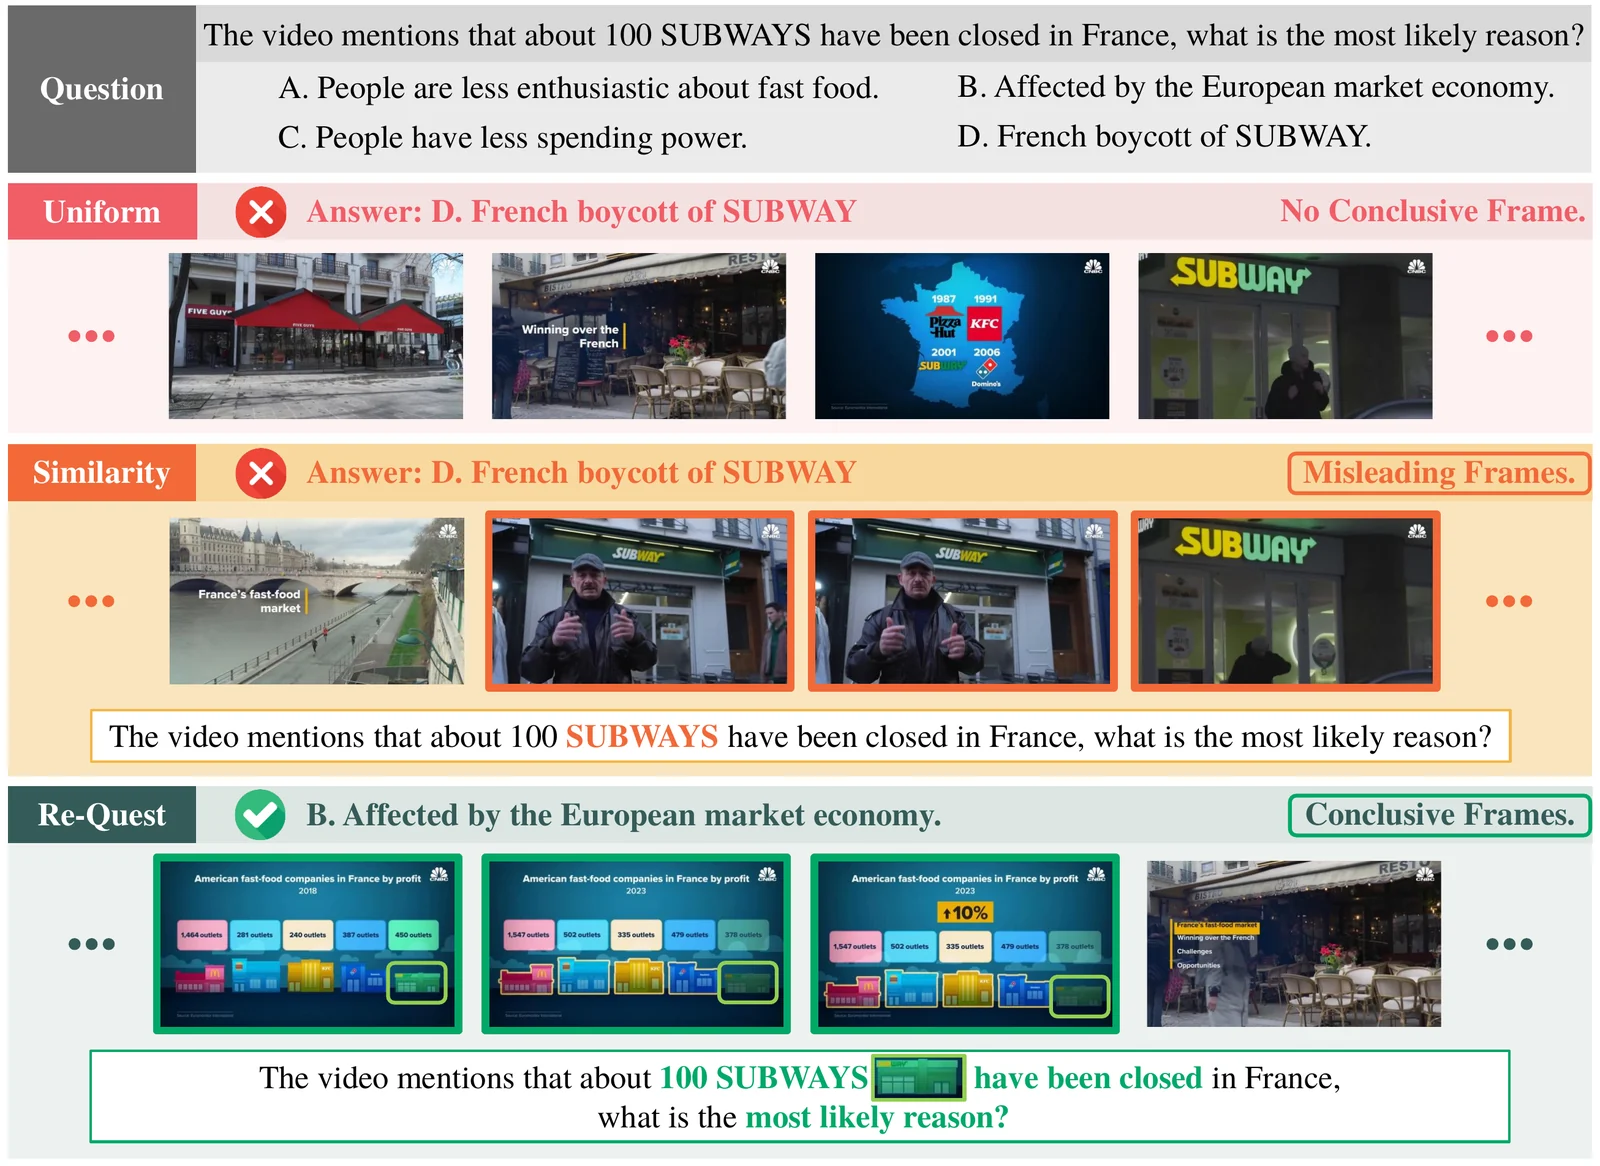
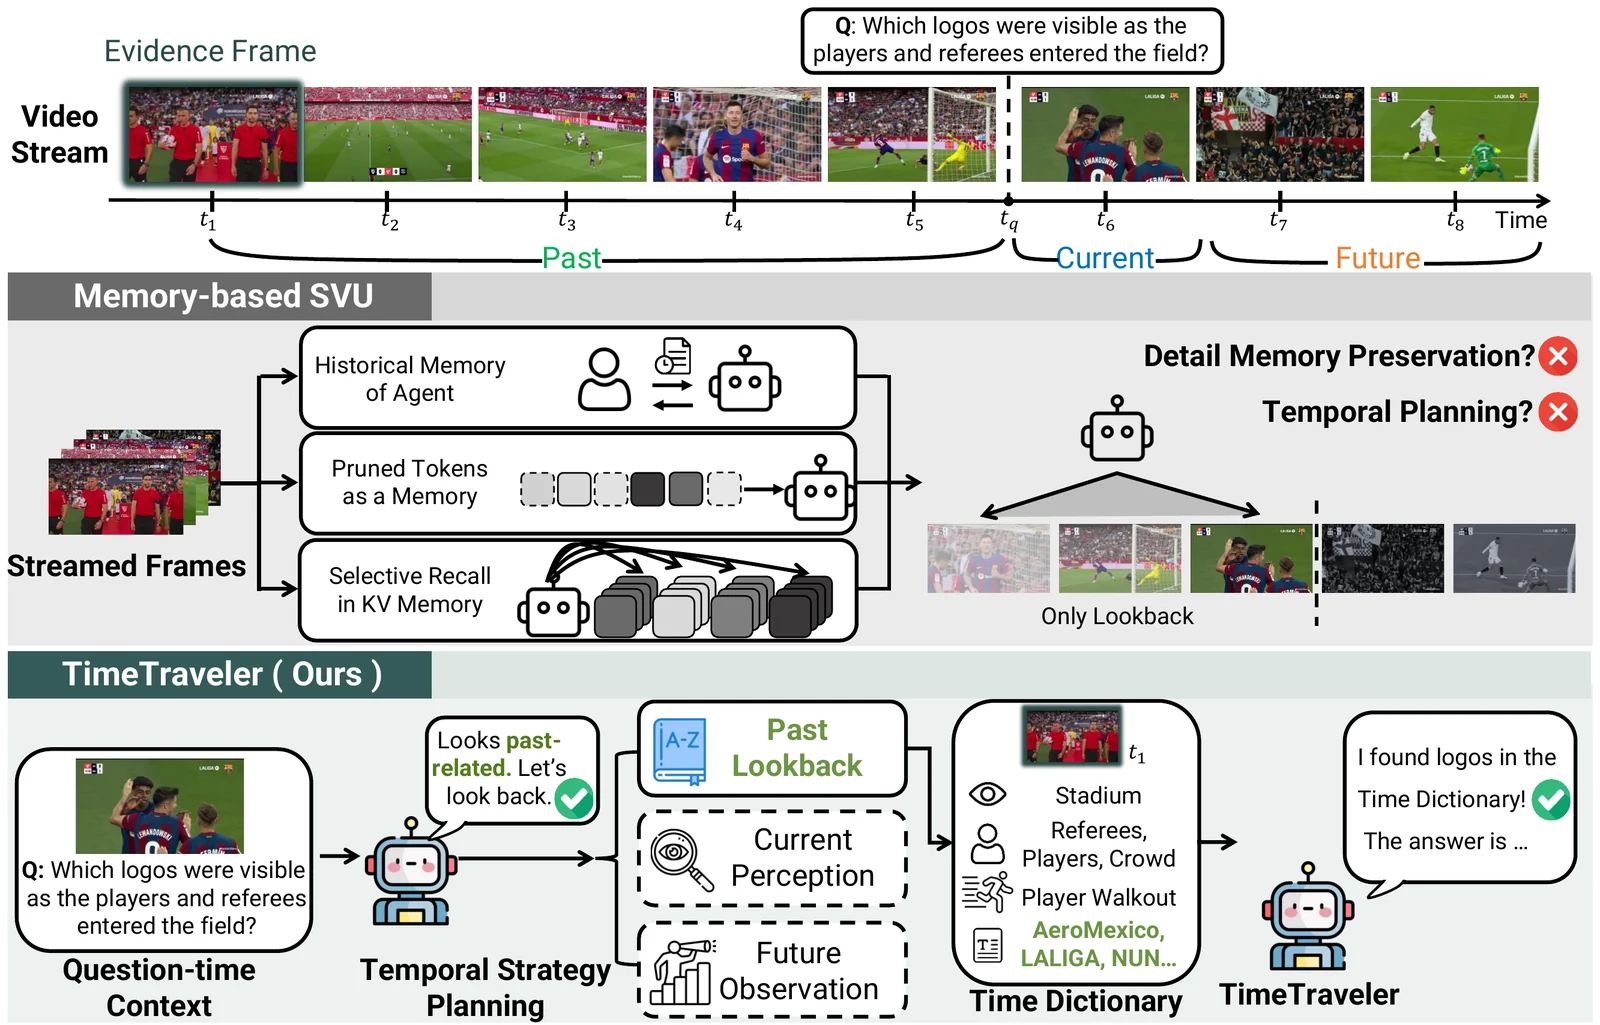
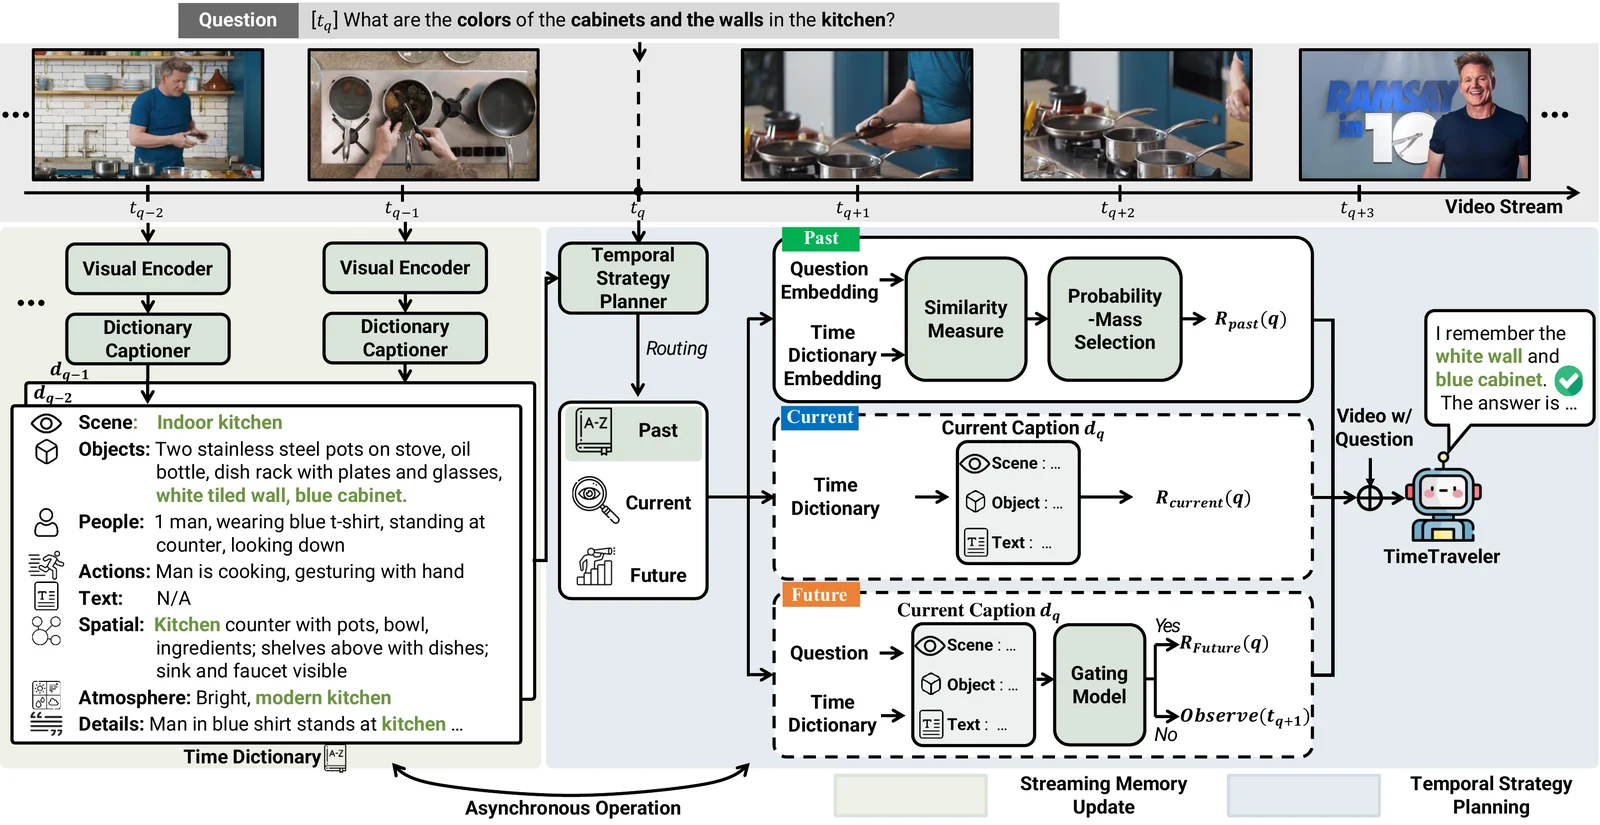
TimeTraveler: a question can point to past, current or future evidence in a video stream; existing memory-based systems only look back.TimeTraveler overall framework: the Time Dictionary is built asynchronously from the stream and the Temporal Strategy Planner routes each question to past, current or future evidence.
01 / 02

TimeTraveler: Temporal Strategy Planning with Time Dictionary for Streaming Video Understanding

Minkuk Kim, Junho Kim*, Seong Tae Kim*

Neural Information Processing Systems (NeurIPS), 2026

Look back, look now, or wait. The stream is kept as structured captions rather than compressed features, so long horizons lose no fine detail; an 8-bit captioner and a small retrieval budget keep every answer under a second at 1 fps.

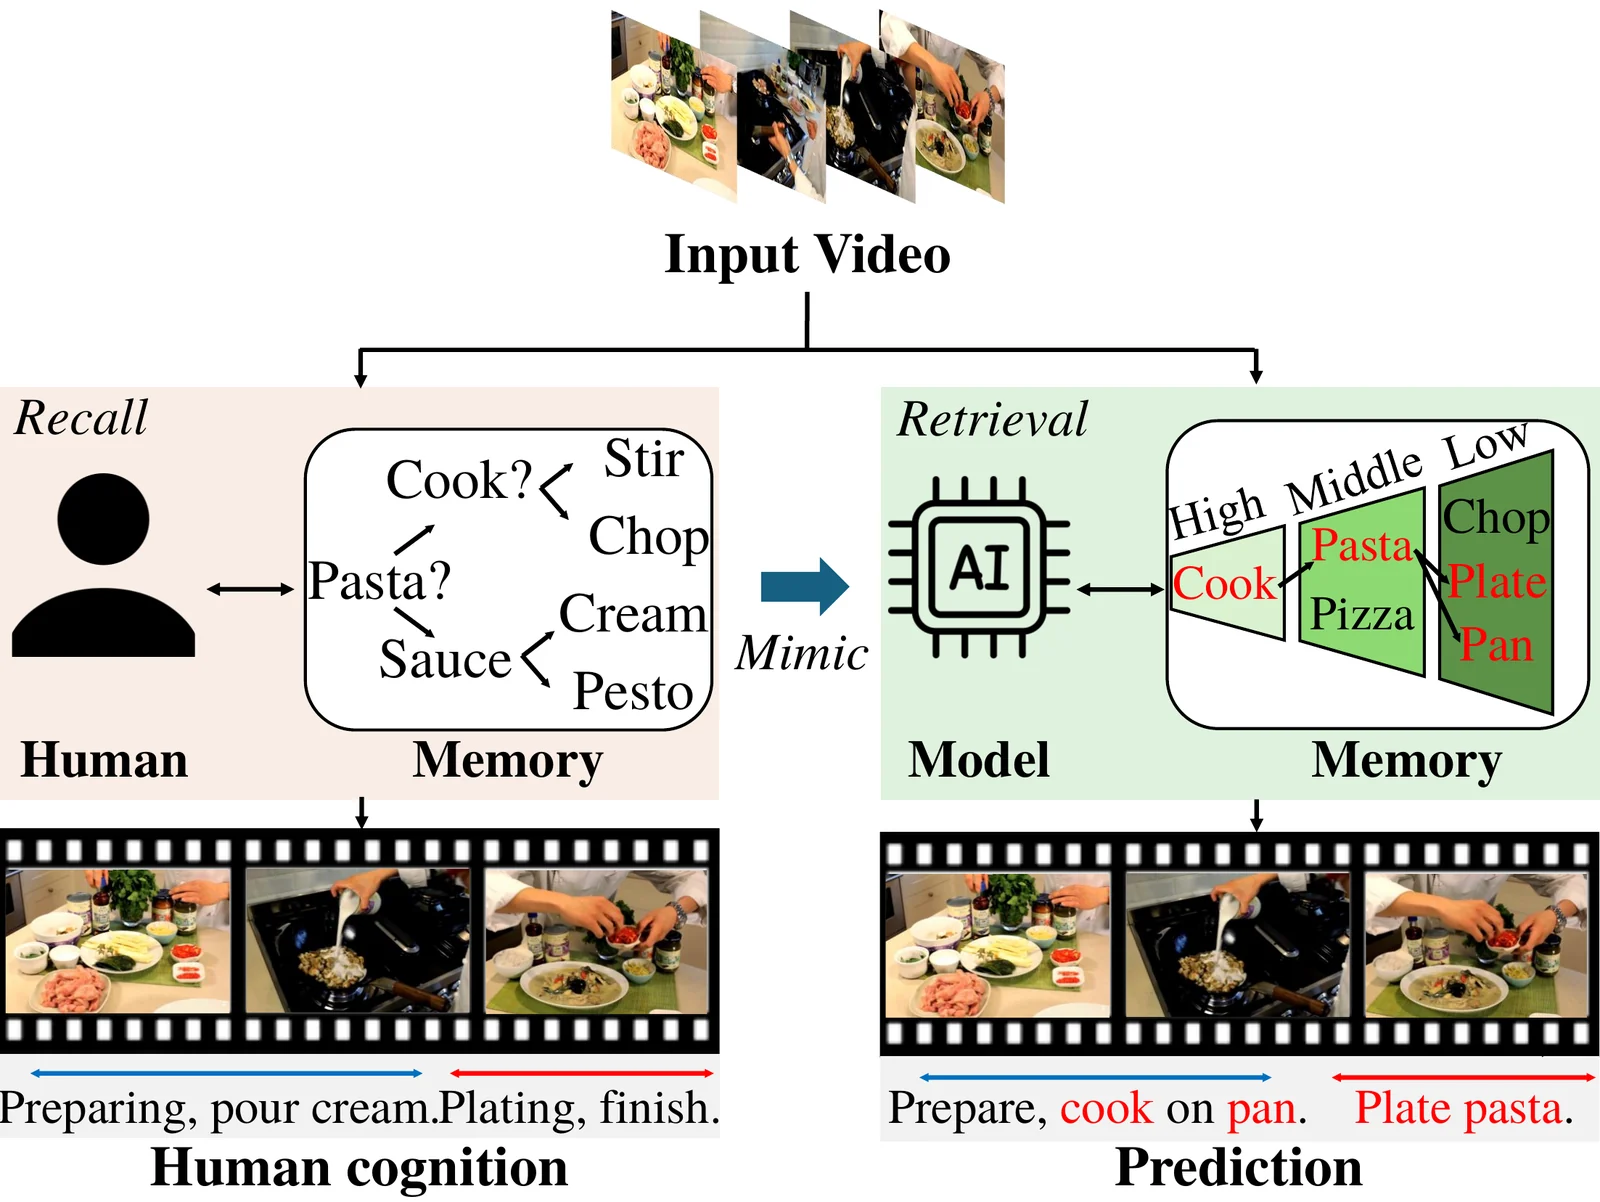
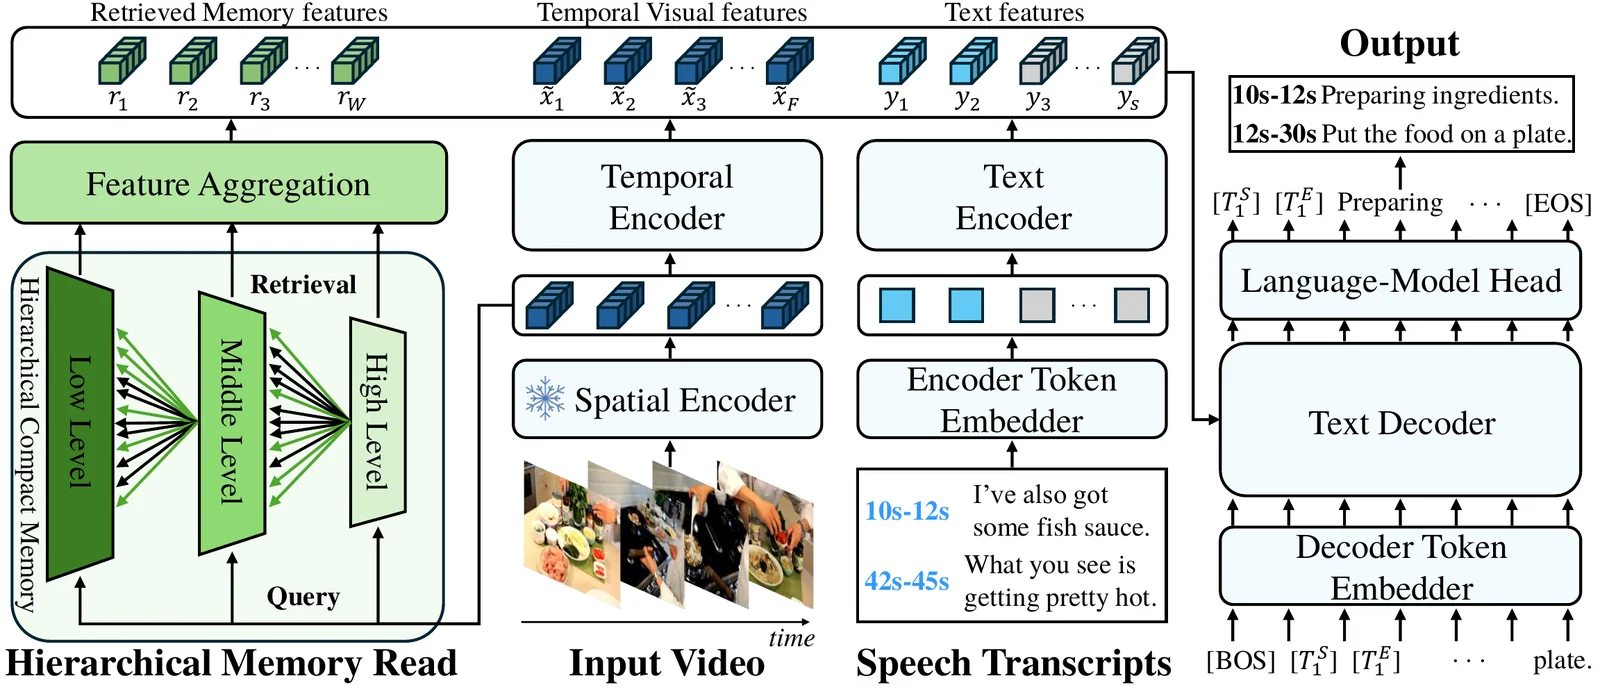
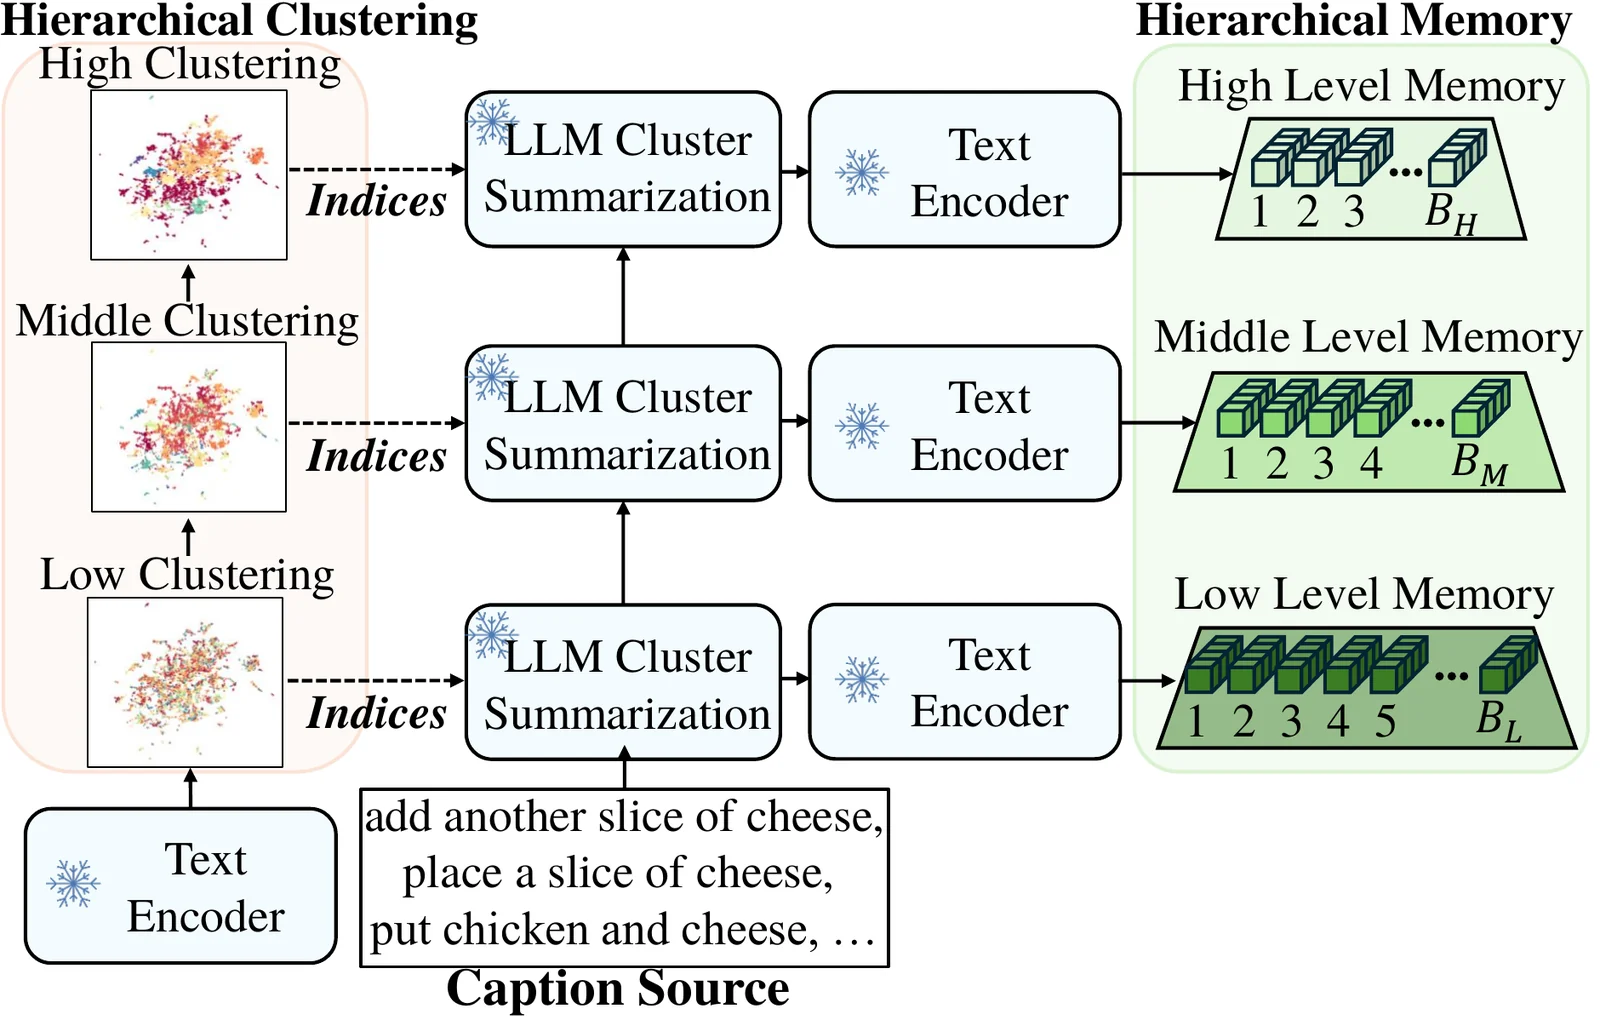
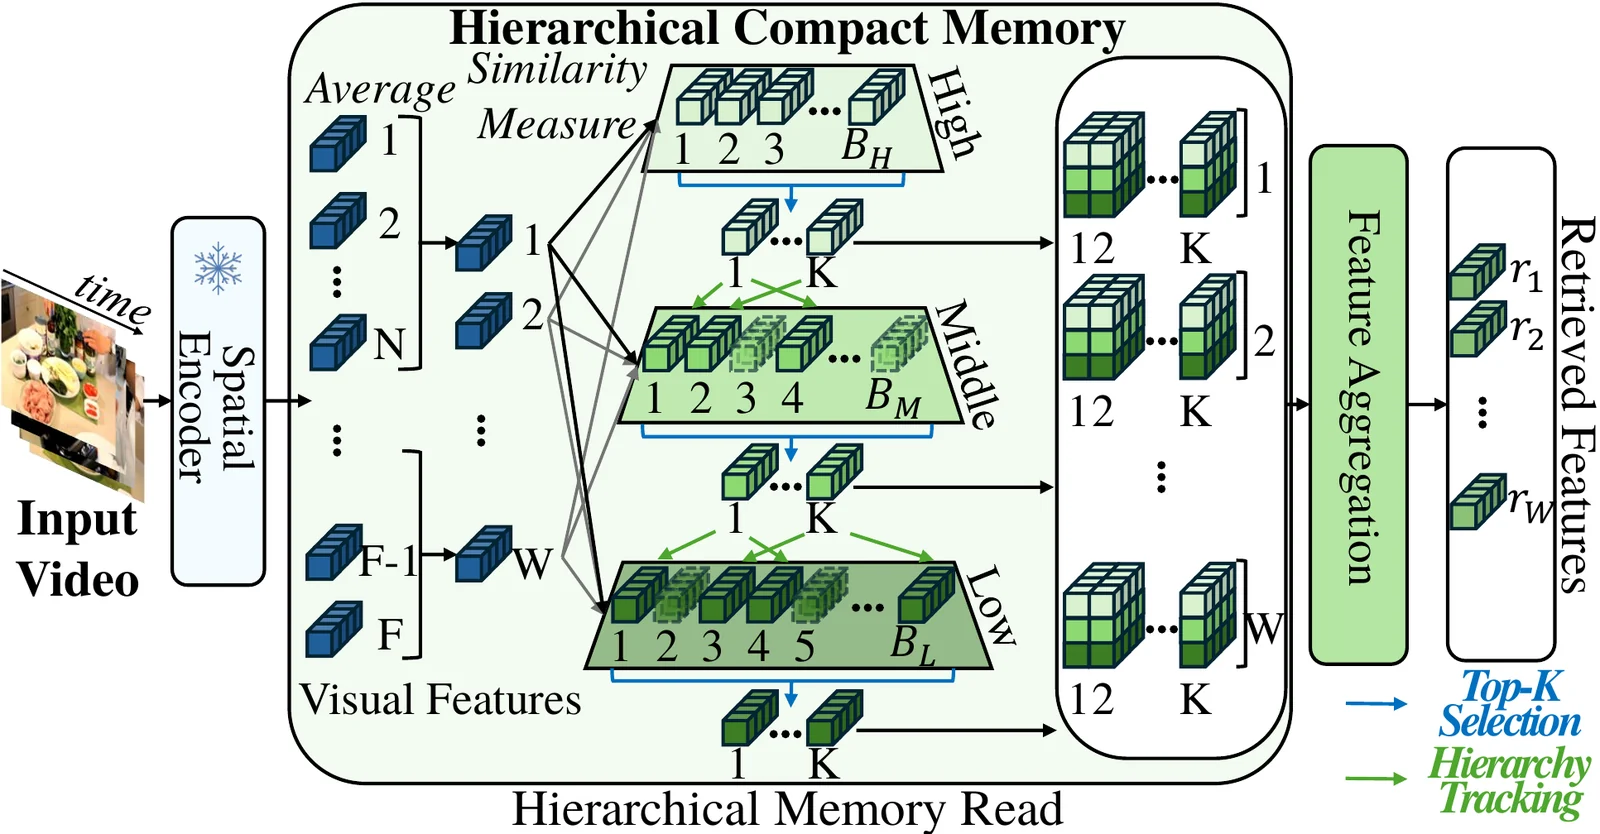
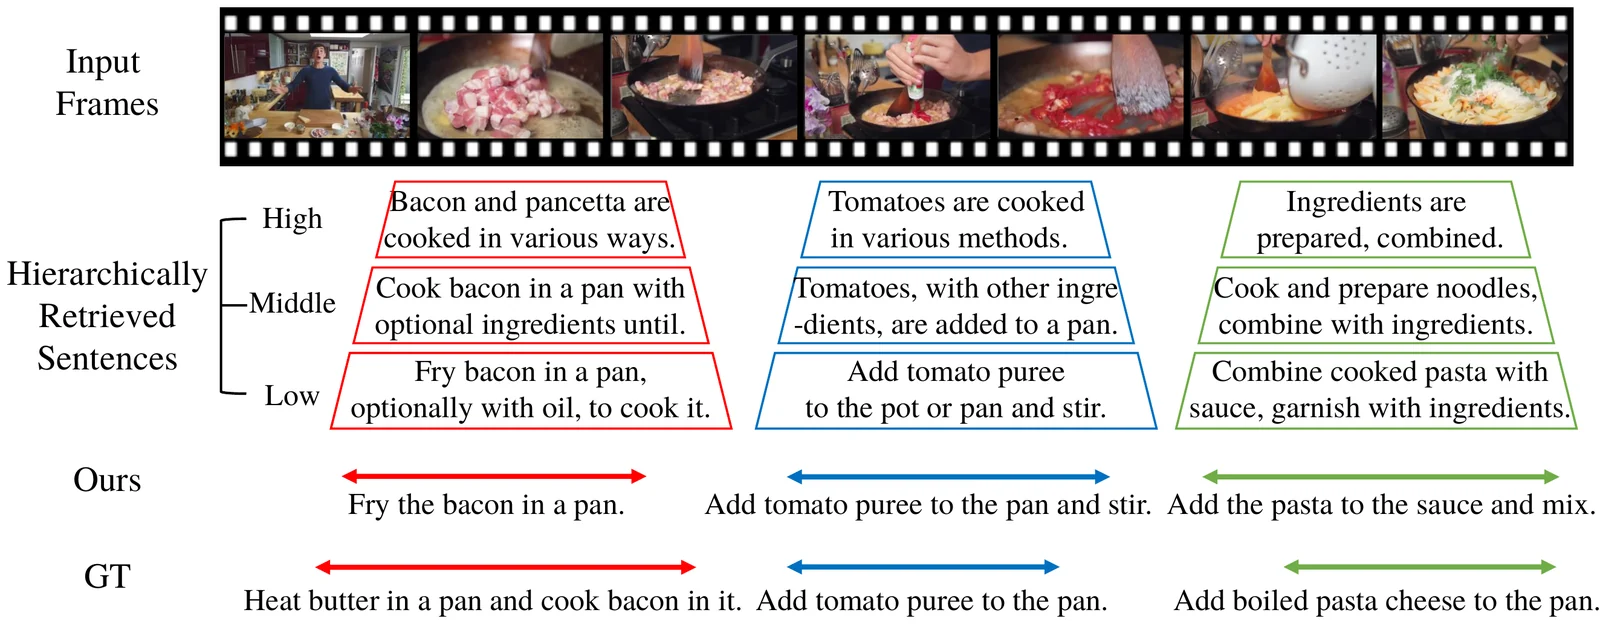
HiCM² motivation: human recall from memory versus model retrieval from a hierarchical memory.HiCM² overall architecture with hierarchical memory read, temporal and text encoders, and a text decoder.Hierarchical memory construction by clustering and LLM cluster summarization.Hierarchical memory read with top-k selection and hierarchy tracking.Qualitative example of hierarchically retrieved sentences and generated captions.
01 / 05

HiCM²: Hierarchical Compact Memory Modeling for Dense Video Captioning

Minkuk Kim, Hyeon Bae Kim, Jinyoung Moon, Jinwoo Choi*, Seong Tae Kim*

AAAI Conference on Artificial Intelligence (AAAI), 2025

Memory in layers, the way people keep it. Captions are clustered and summarized into low, middle and high levels of abstraction, so a long video is recalled coarse-to-fine instead of searched flat. Compact, hierarchical memory of the kind long-horizon agents need, worked out on dense video captioning.

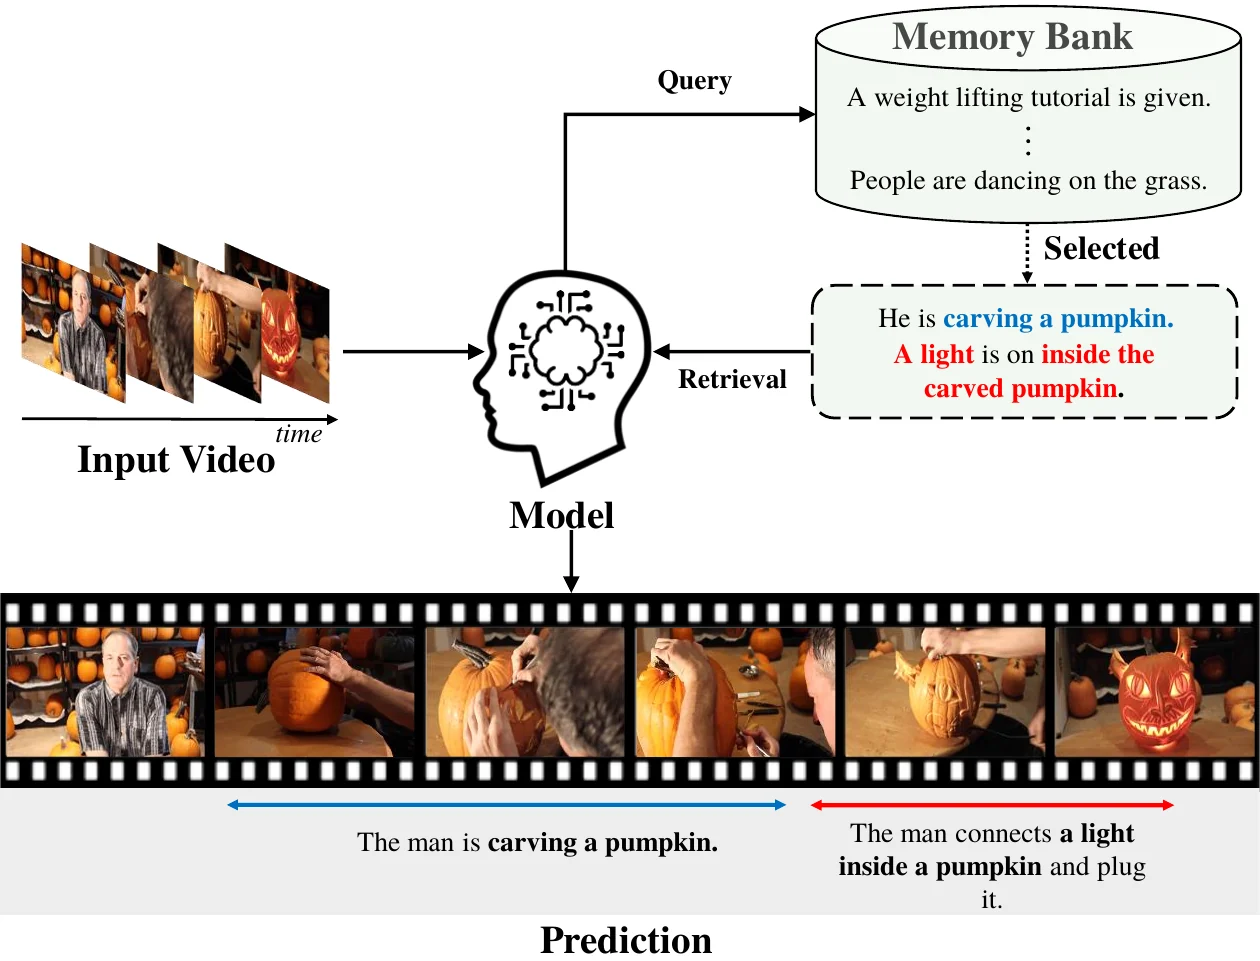
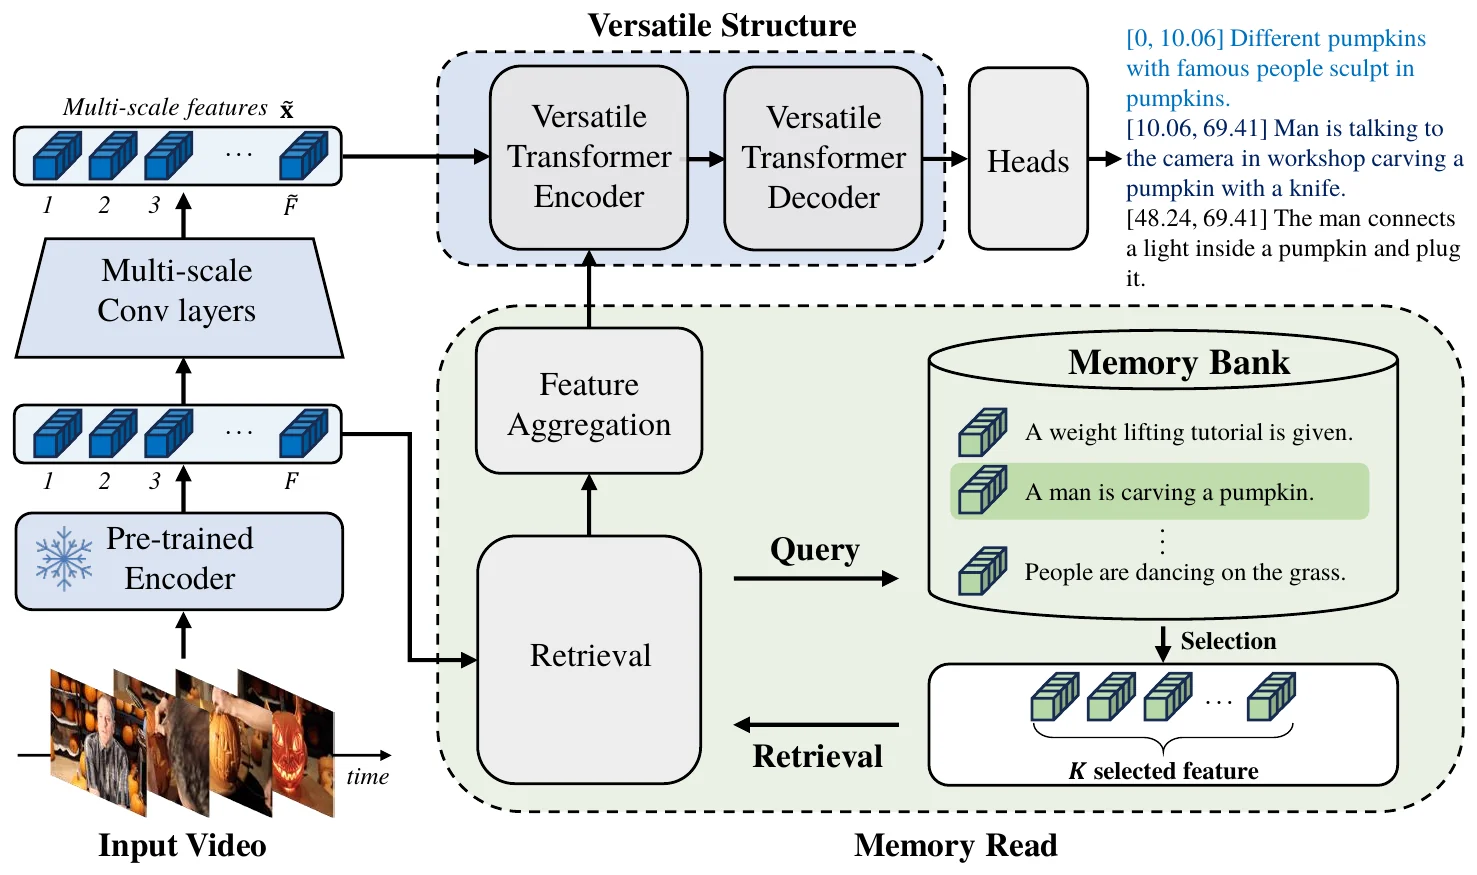
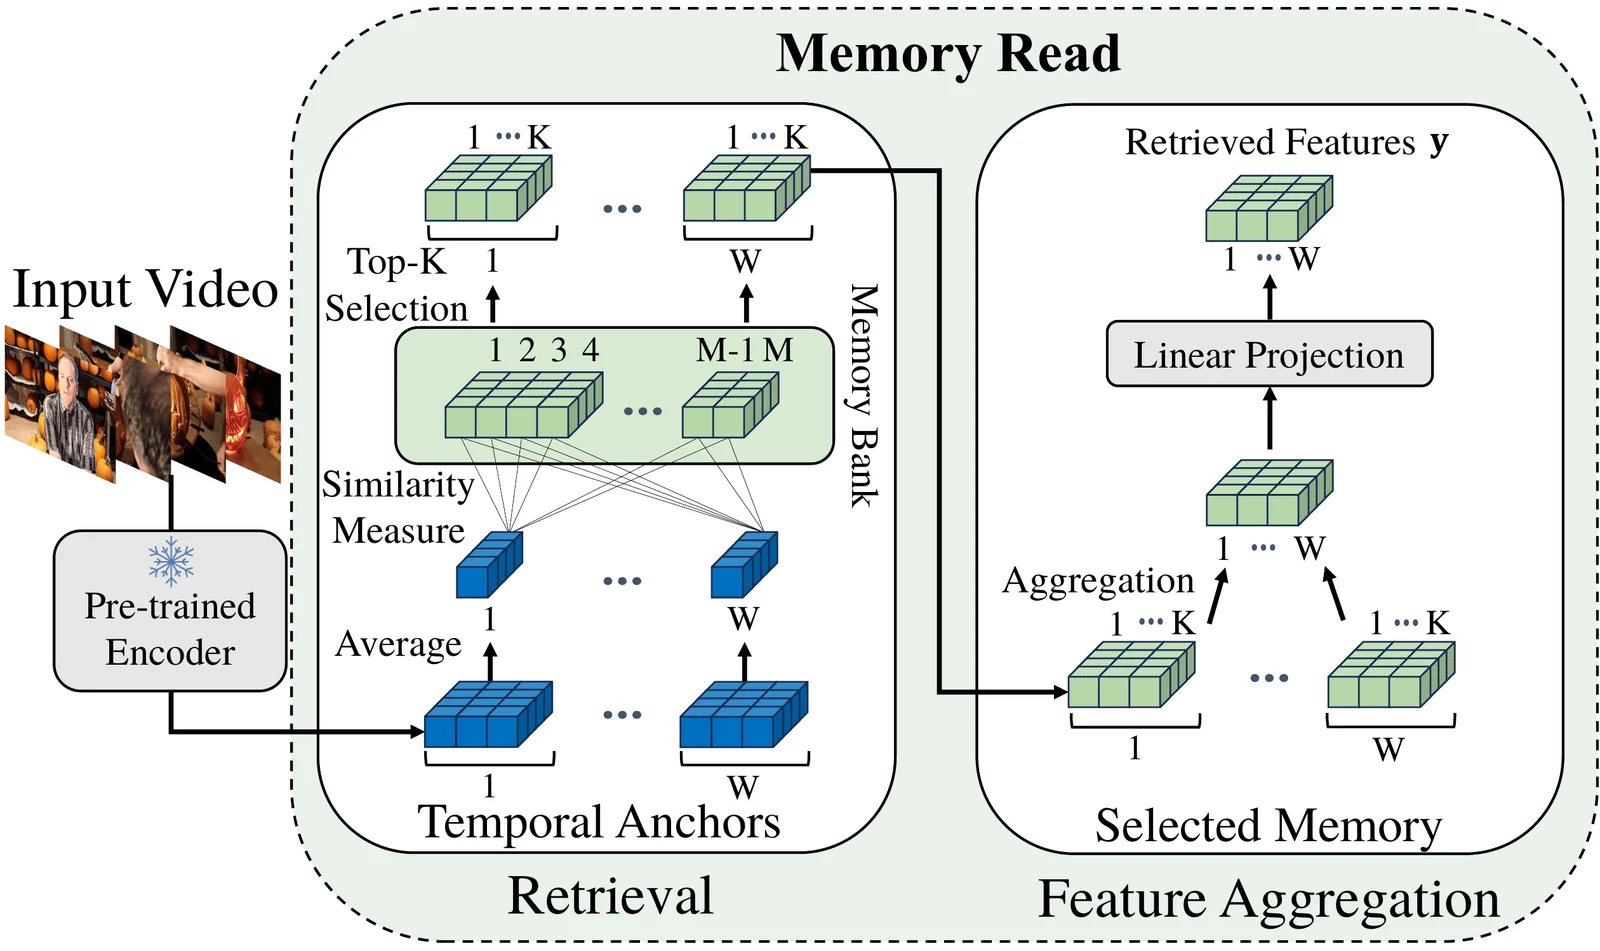
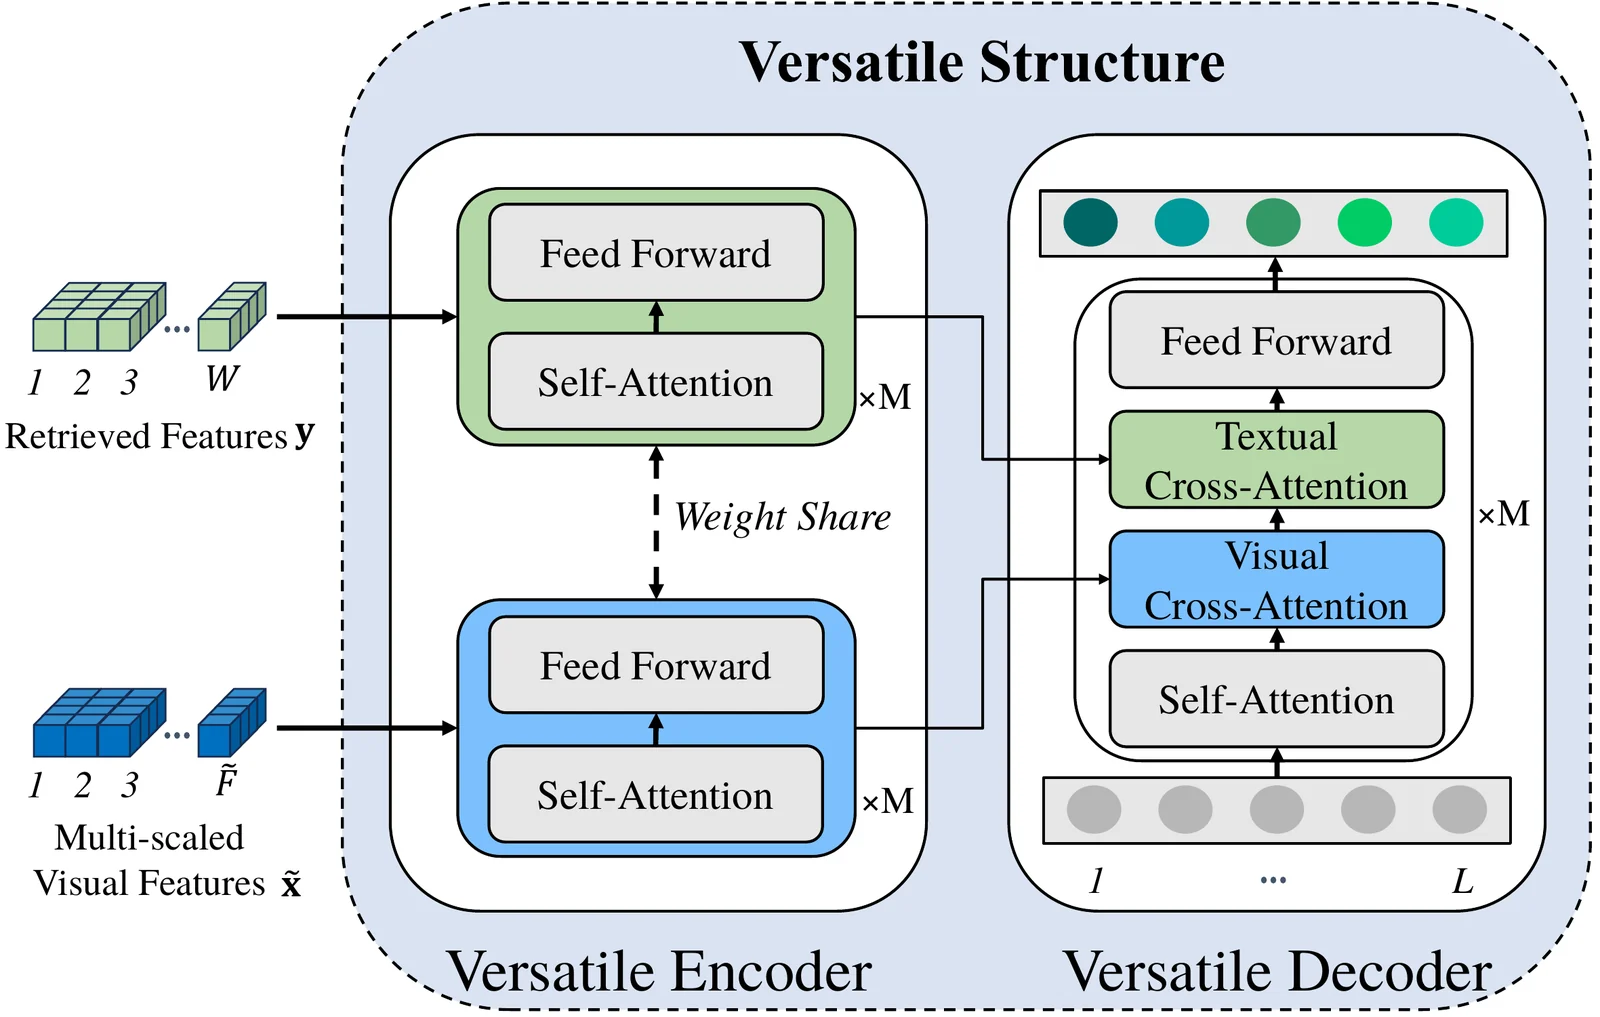
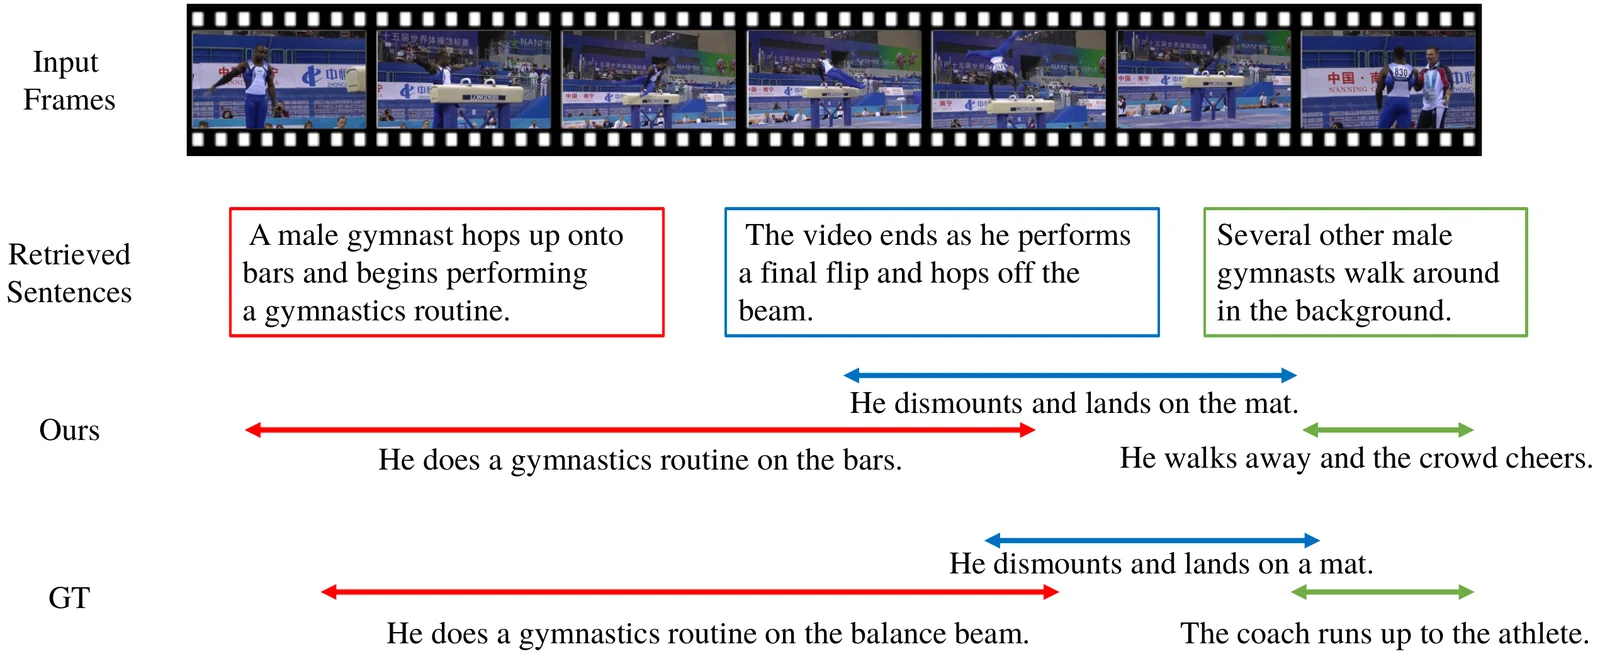
CM² concept: the model queries an external memory bank and retrieves relevant sentences to caption the video.CM² overall architecture with memory read and a versatile encoder-decoder.Memory read: retrieval with temporal anchors and feature aggregation.Versatile encoder and decoder with visual and textual cross-attention.Qualitative example of retrieved sentences and generated captions.
01 / 05

Do You Remember? Dense Video Captioning with Cross-Modal Memory Retrieval

Minkuk Kim, Hyeon Bae Kim, Jinyoung Moon, Jinwoo Choi*, Seong Tae Kim*

IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024

Recall before you describe. An external memory of sentences is retrieved against what the model sees, and the recalled cues guide both where an event is and how to say it. Retrieval-augmented generation, for video: where this line of work began.

* Corresponding author  ·  † Equal contribution