CVPR 2024, Seattle CVPR 2024 · AAAI 2025

CM² · HiCM² Memory-Augmented Dense Video Captioning

Two papers on giving a dense video captioner a memory to recall from. CM² retrieves sentences from a flat memory of training captions. HiCM² organizes that memory into a hierarchy of compact summaries and reads it from the top down.

Minkuk Kim1,  Hyeon Bae Kim1,  Jinyoung Moon2,  Jinwoo Choi1*,  Seong Tae Kim1*
1Kyung Hee University 2Electronics and Telecommunications Research Institute (ETRI)
*Corresponding authors

From a flat memory to a hierarchy

Dense video captioning has to find every event in an untrimmed video and describe each one. Visual features alone carry little semantic content for that. Both papers take a cue from how people describe what they see: by recalling something similar they have seen before.

Chapter I · CVPR 2024
CM²

Do You Remember? Dense Video Captioning with Cross-Modal Memory Retrieval

Overview

CM² stores the training captions as an external memory. The input video is split into segment-level temporal anchors, and each anchor retrieves its most similar sentences through video-to-text matching. A versatile encoder processes the visual features and the retrieved text with shared weights, and the decoder reads them through separate visual and textual cross-attention to predict event boundaries and captions.

Without pretraining on extra videos, CM² reaches 33.01 CIDEr on ActivityNet Captions, above Vid2Seq, which is pretrained on 15M videos.
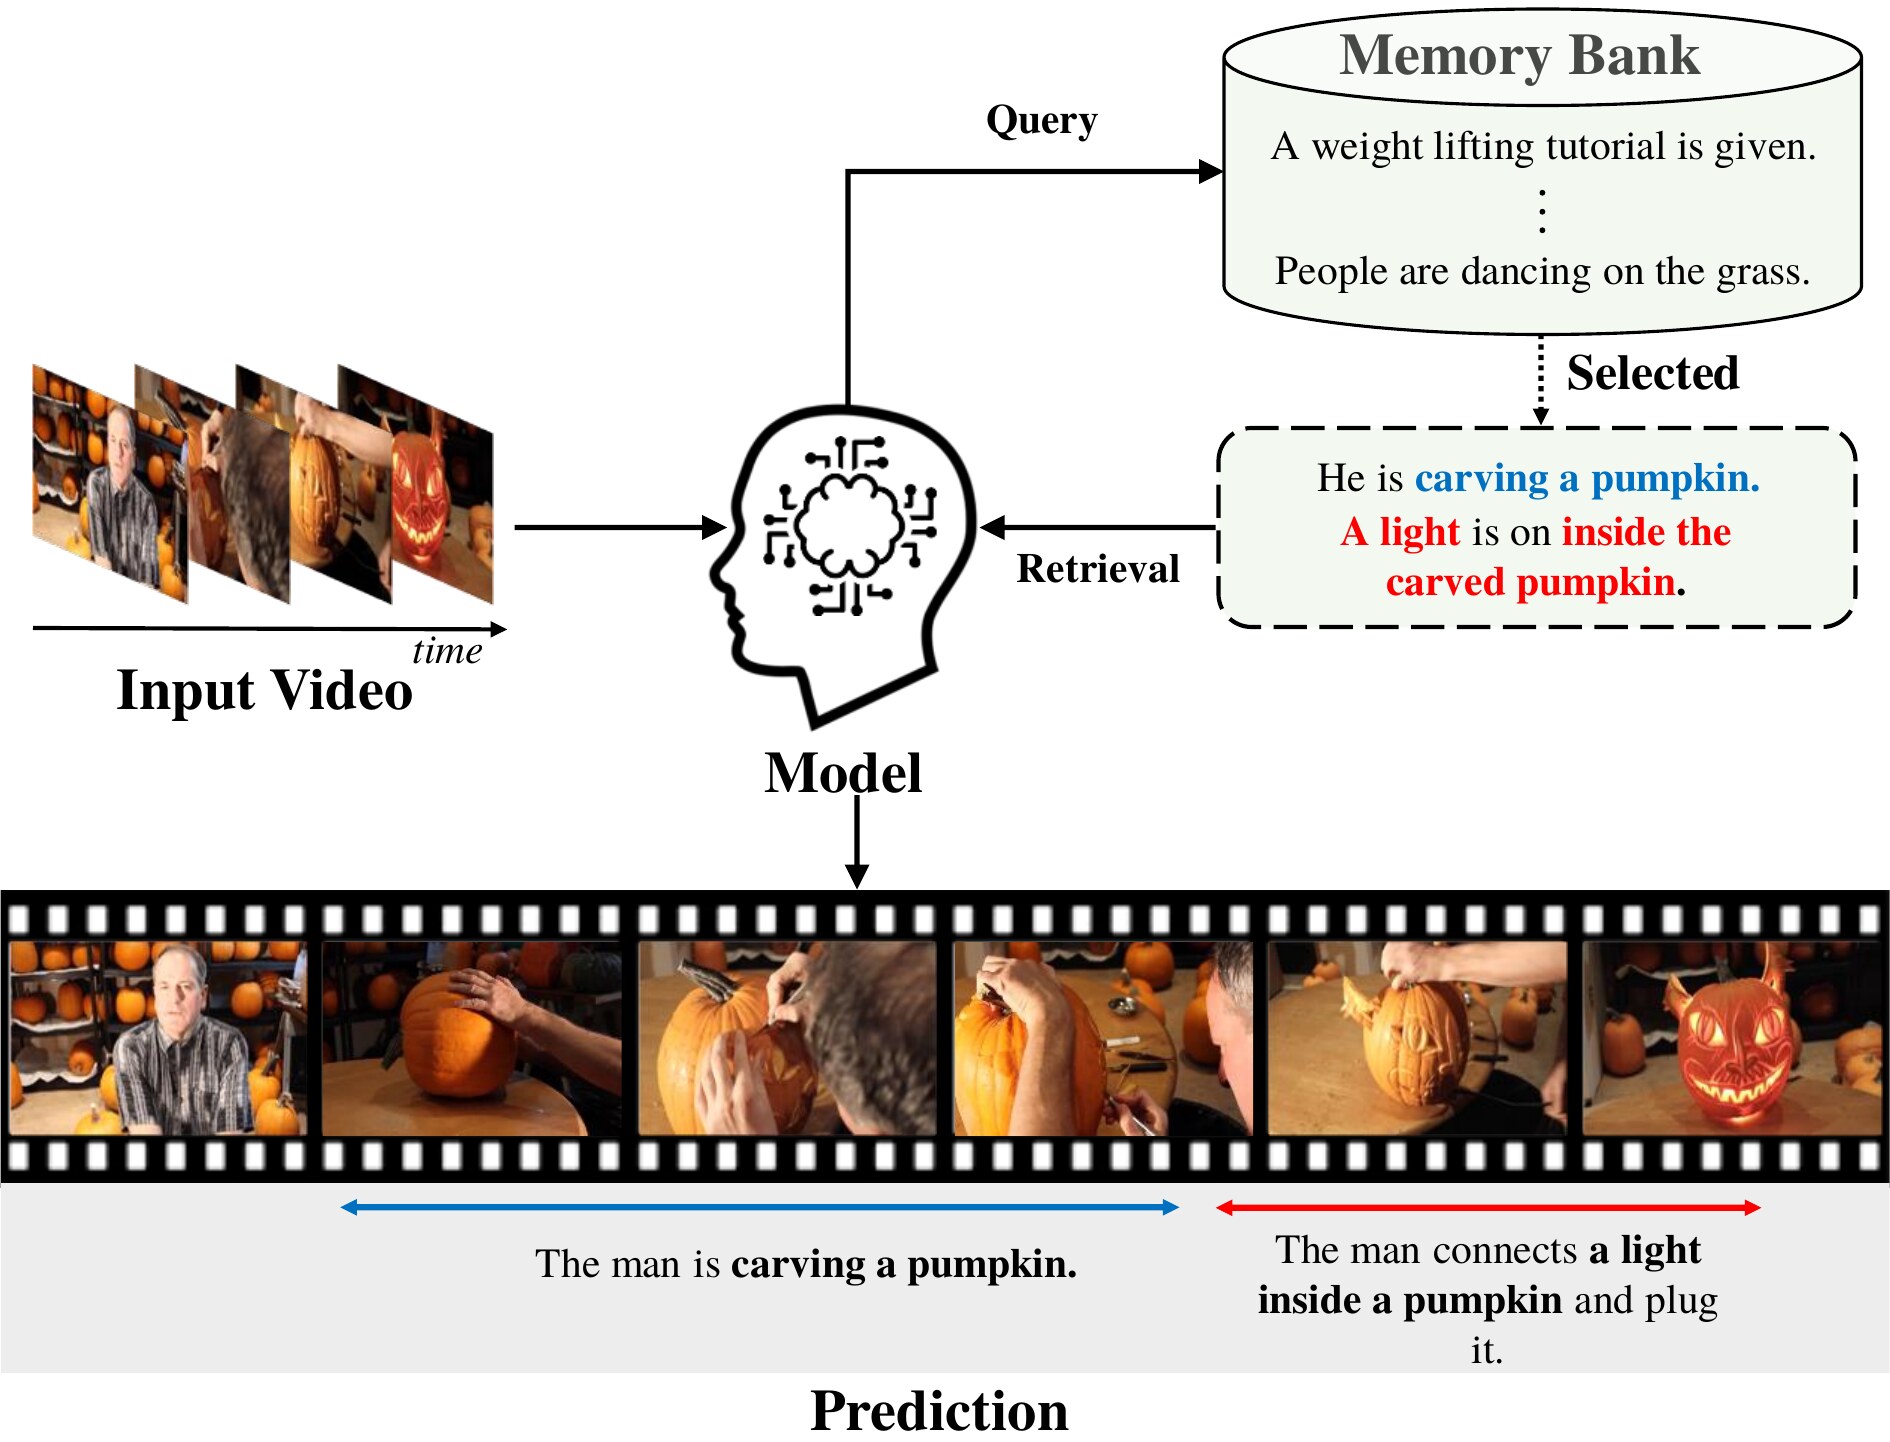
CM² concept: like a person recalling relevant memories, the model searches an external memory bank for relevant sentences to describe and localize events in an untrimmed video.
Recall, then describe. CM² searches an external memory bank for clues relevant to each part of the video, and uses them to describe and localize events.

See it in action

Method

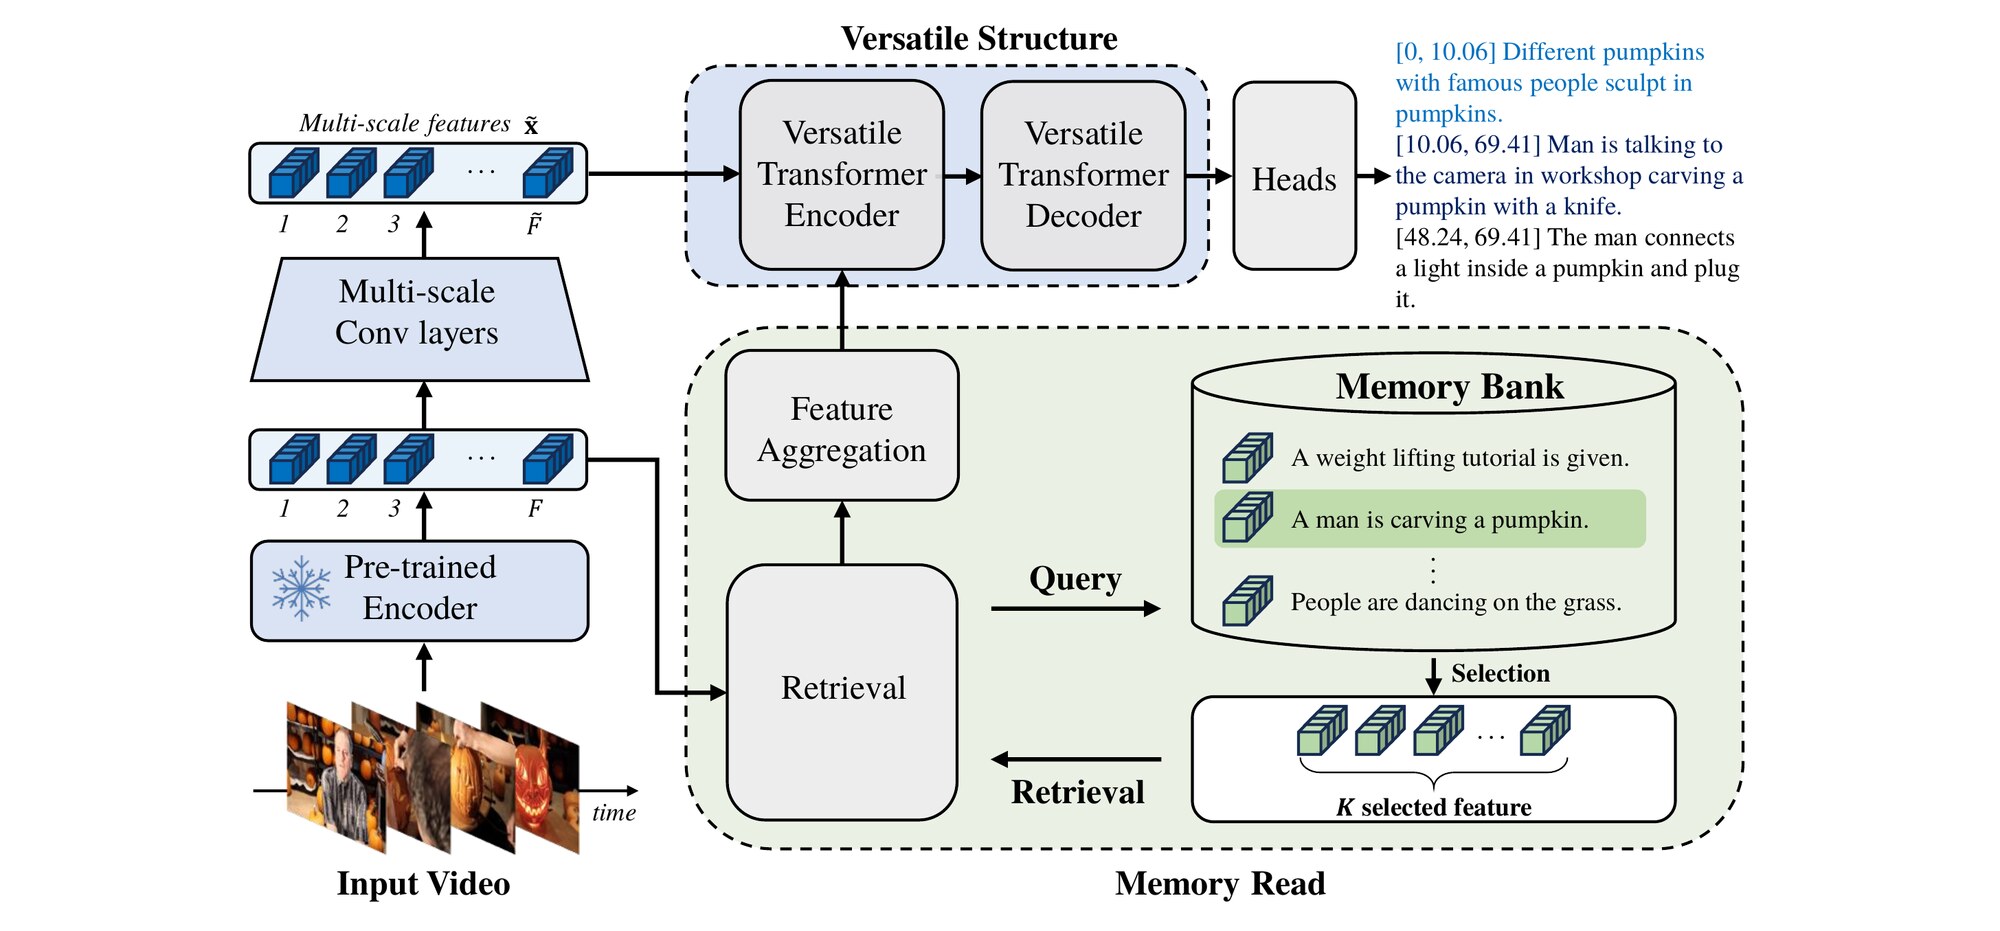
CM² overall architecture: a frozen CLIP image encoder, memory retrieval with temporal anchors, a versatile transformer encoder, and a decoder with visual and textual cross-attention that outputs start time, end time, and caption.
Overall architecture. Video features query the memory; retrieved text and visual features go through a shared encoder, and the decoder attends to both before predicting each event.
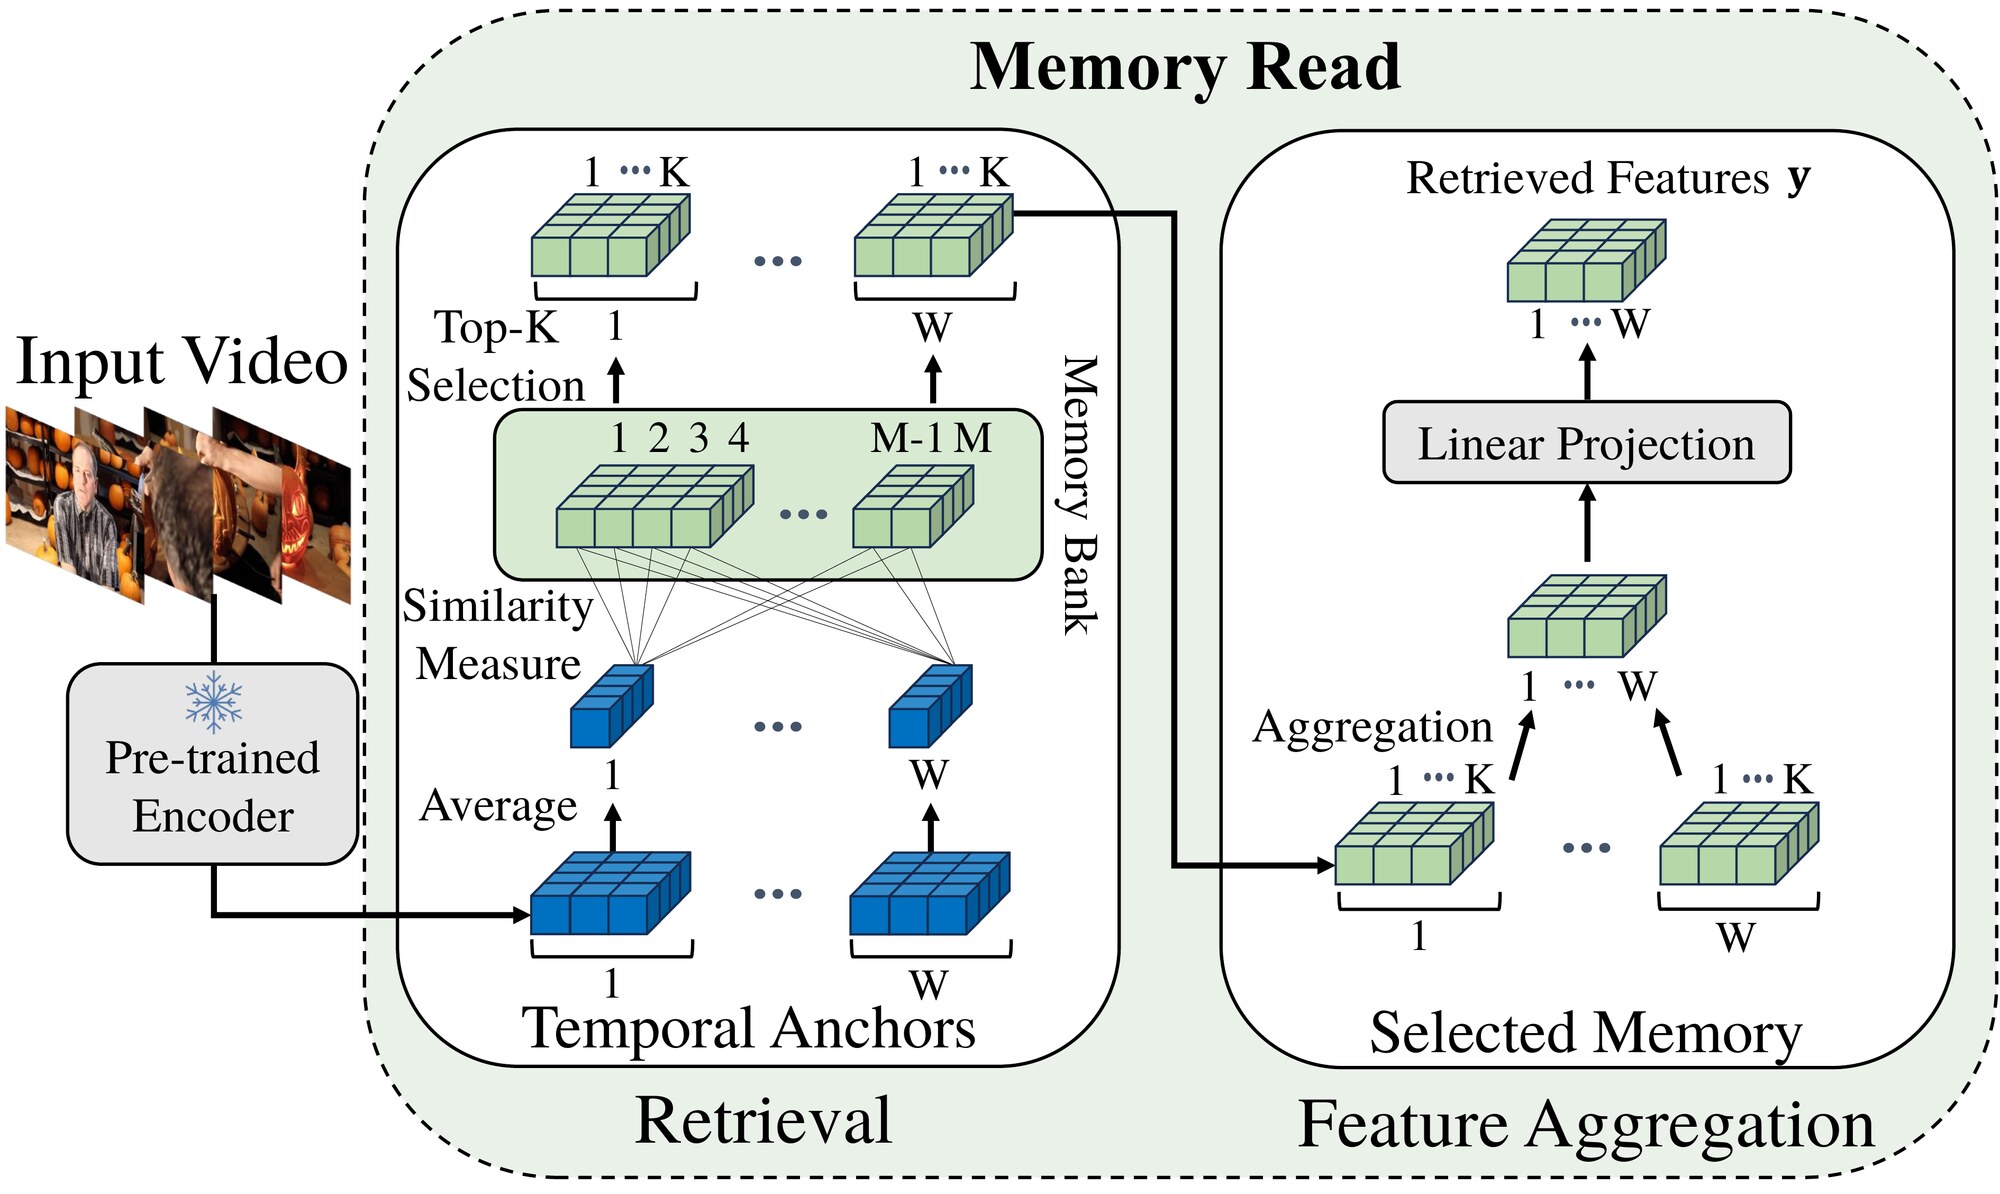
Memory read module: temporal anchors are compared with the text features in memory, and the top-k retrieved features are aggregated per anchor.
Memory read. Segment-level anchors retrieve and aggregate their nearest text features.
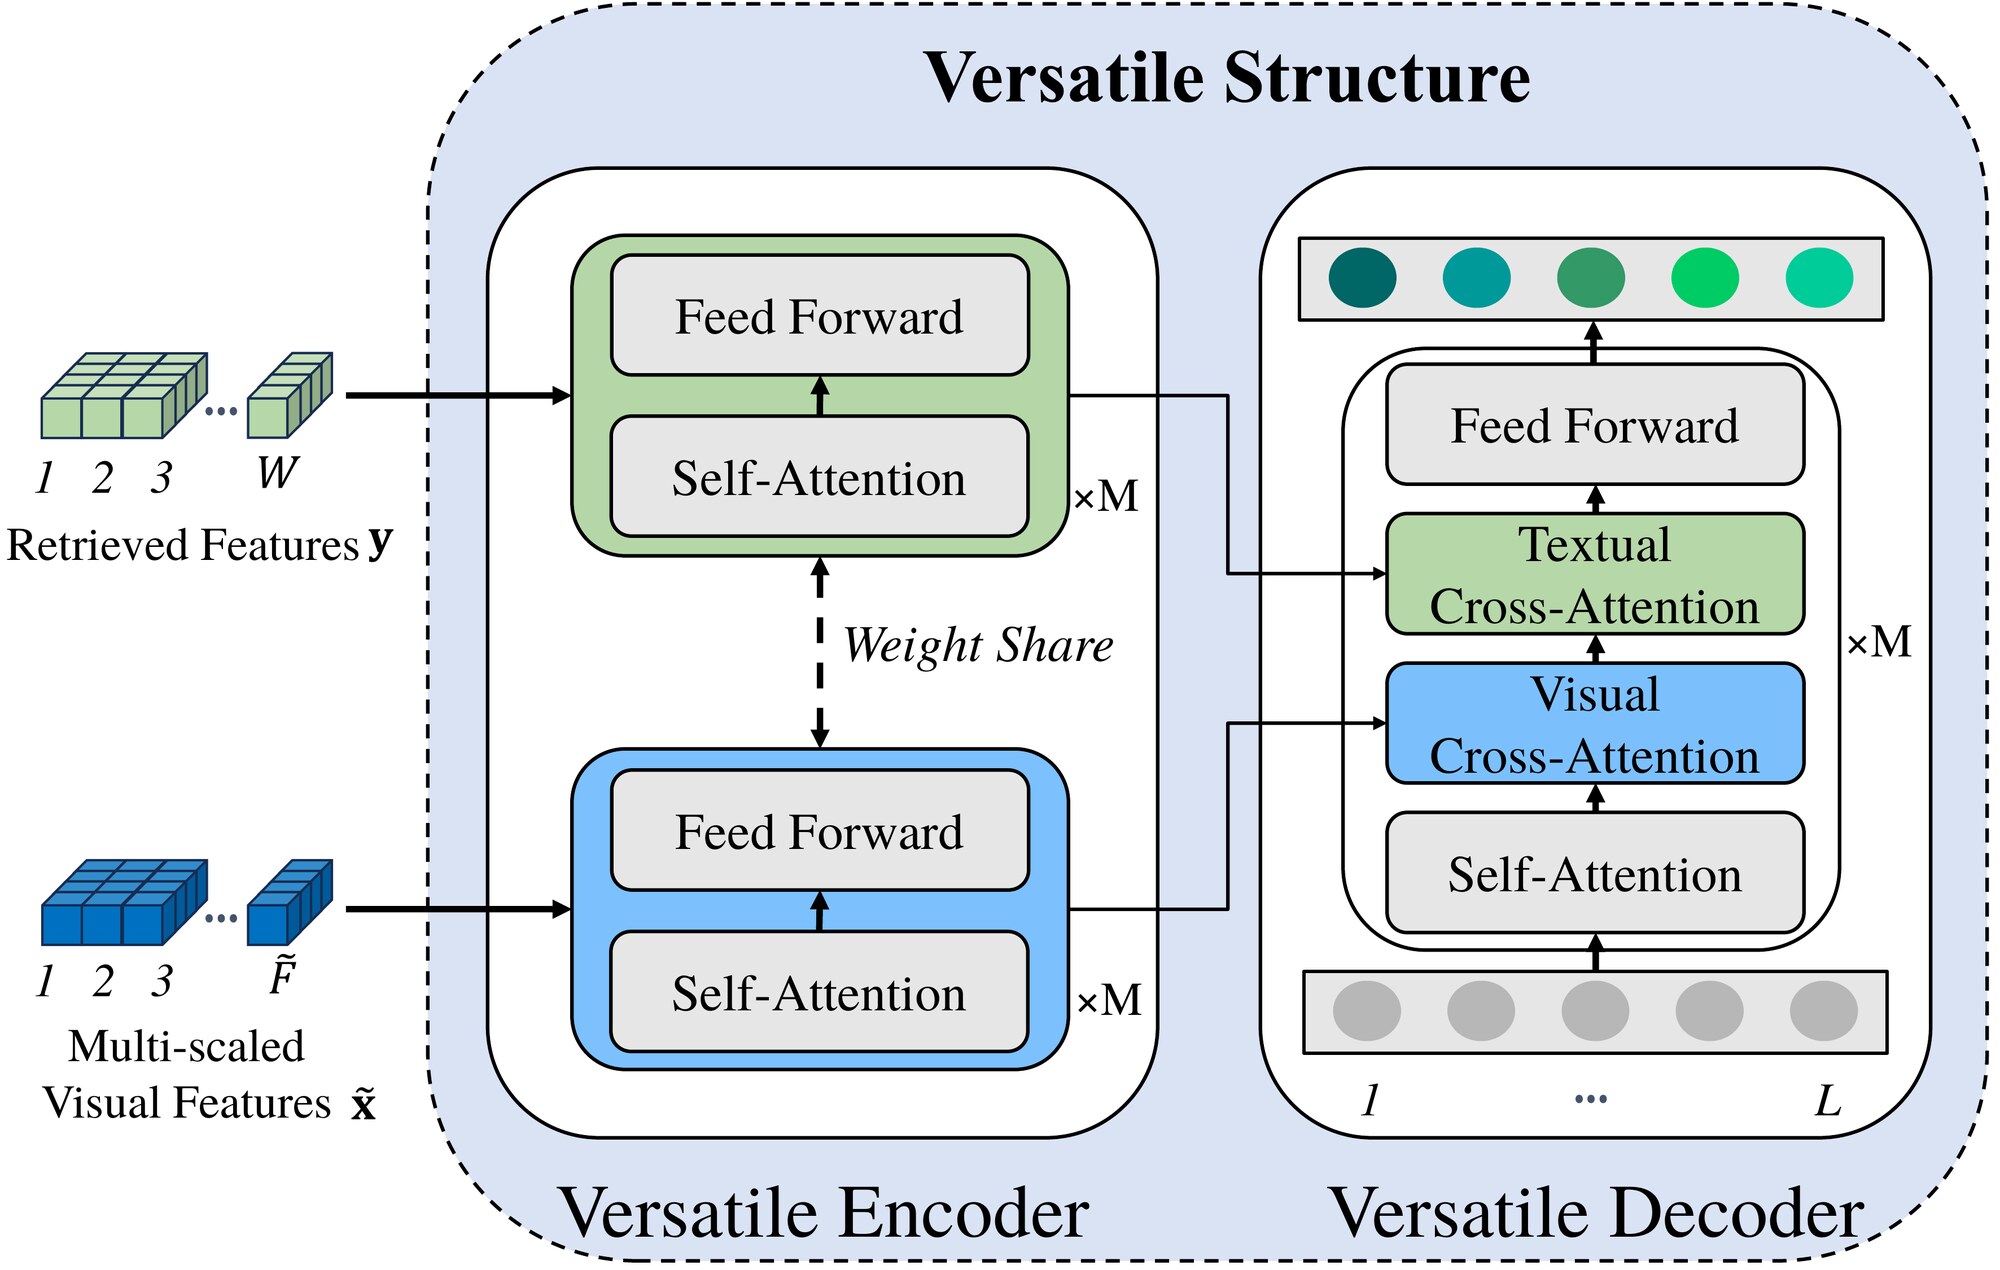
Versatile encoder-decoder: one weight-shared encoder for visual and text features, and a decoder with separate visual and textual cross-attention.
Versatile encoder-decoder. One weight-shared encoder for both modalities; separate cross-attention for each.

Results

ActivityNet Captions · CIDEr
Without → with memory retrieval31.24 →33.01+1.77
YouCook2 · CIDEr
Without → with memory retrieval23.67 →31.66+7.99

Event captioning, ActivityNet Captions

MethodBackbone#PT videosCIDErMETEORBLEU4SODA_c
Vid2SeqCLIP15M30.108.50–5.80
MTTSN–6.103.200.30–
ECHRC3D–14.707.201.823.20
UEDVCC3D––––5.5
PDVC†CLIP–29.978.062.215.92
CM² (ours)CLIP–33.018.552.386.18

Event captioning, YouCook2

MethodBackbone#PT videosCIDErMETEORBLEU4SODA_c
Vid2SeqCLIP1M47.109.30–7.90
MTTSN–9.305.001.15–
ECHRC3D––3.82––
E2ESGC3D–25.003.50––
PDVC†CLIP–29.695.561.404.92
CM² (ours)CLIP–31.666.081.635.34

Event localization

MethodPTActivityNet CaptionsYouCook2
F1RecallPrecisionF1RecallPrecision
Vid2Seq✓53.2952.7053.9027.8427.9027.80
PDVC†✗54.7853.2756.3826.8122.8932.37
CM² (ours)✗55.2153.7156.8128.4324.7633.38

Bold and underline mark the best and second best, as in the paper. †Reproduced from the official implementation. #PT videos: extra videos used for pretraining. All methods in the localization table use CLIP features.

How much a good memory could add

If retrieval were perfect (querying the memory with the ground-truth captions and placing the results on ground-truth segments), YouCook2 CIDEr would reach 183.95. CM²'s real retrieval is a first step toward that ceiling.
YouCook2 CIDEr. Oracle rows use the retrieved captions directly as output, without the model.
Chapter II · AAAI 2025
HiCM²

HiCM²: Hierarchical Compact Memory Modeling for Dense Video Captioning

Overview

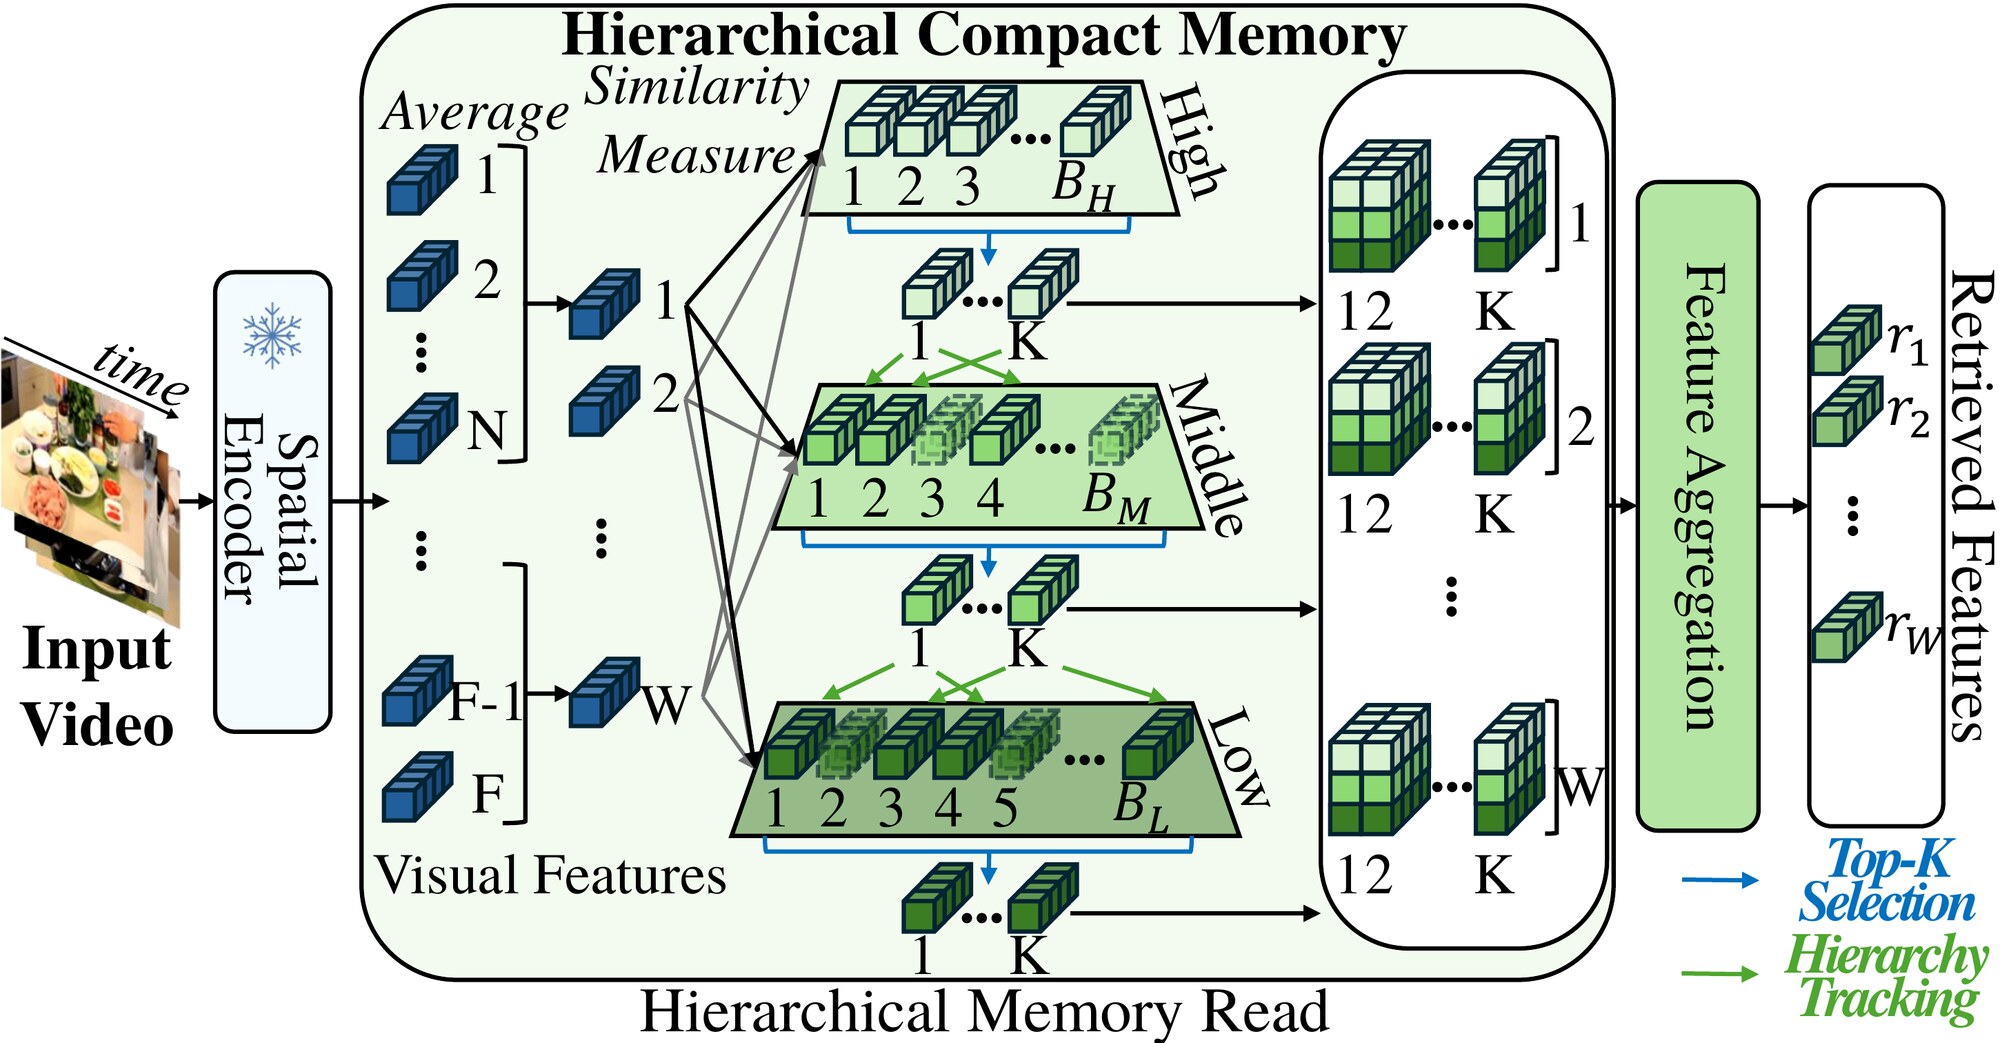
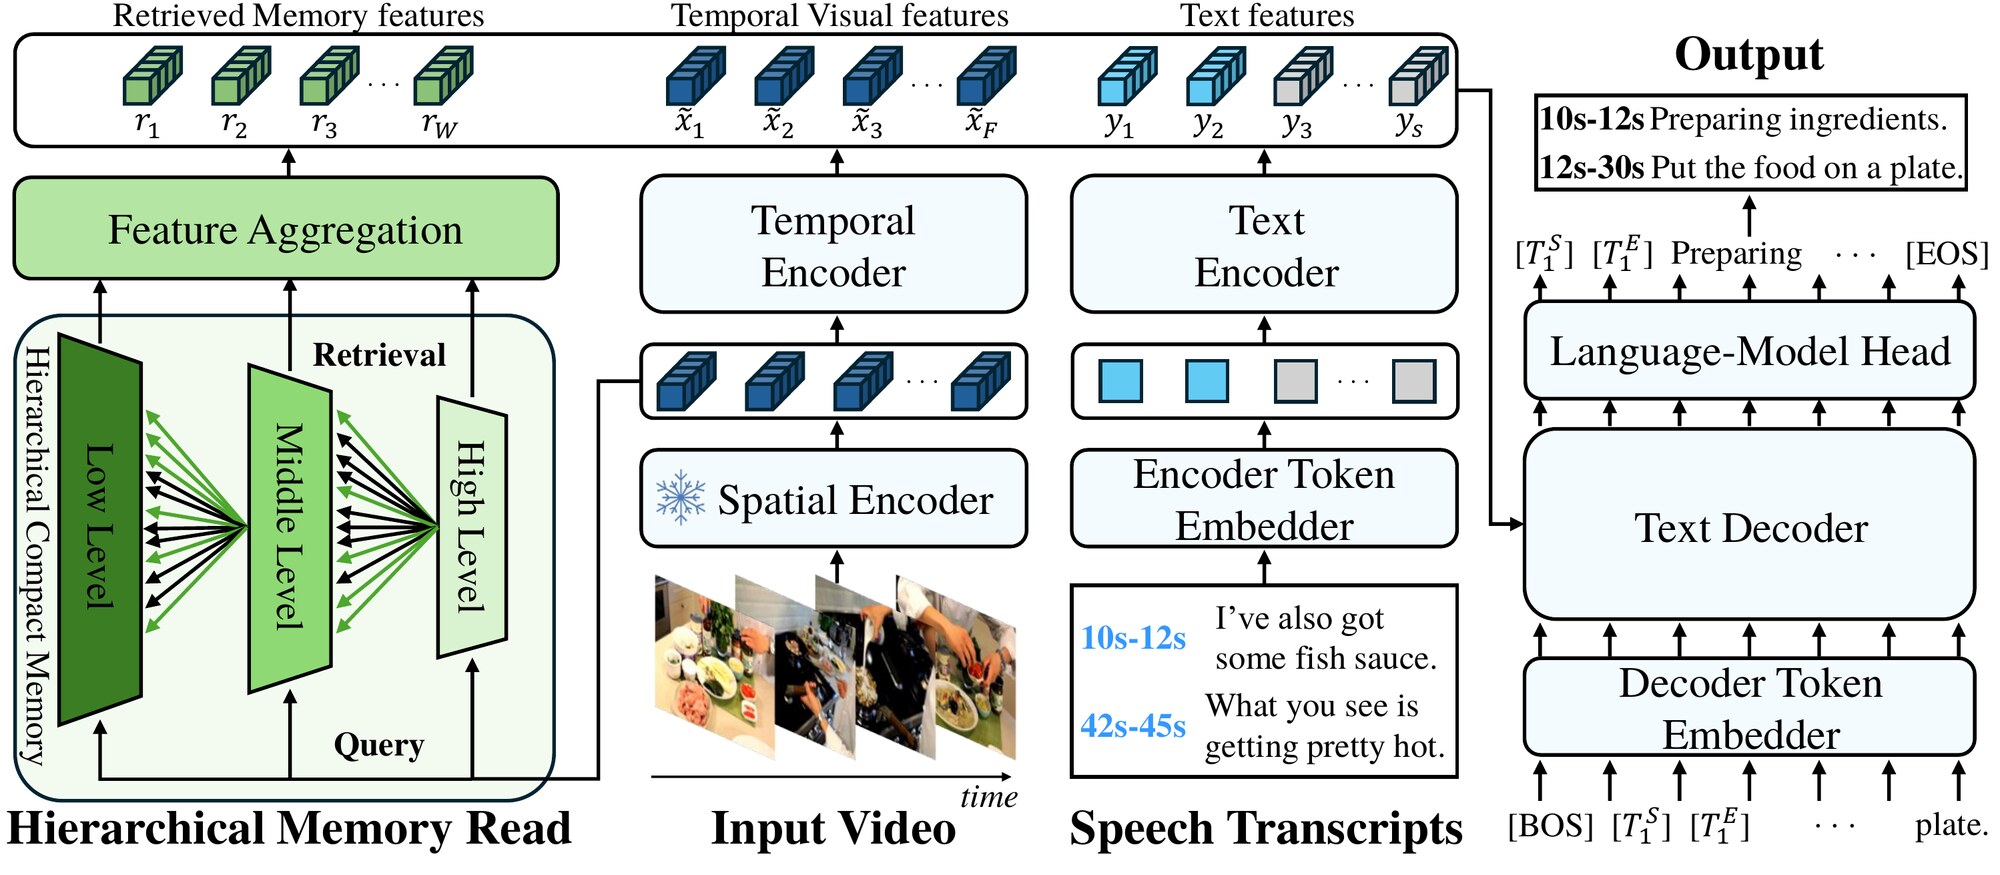
People rarely recall a memory flatly. We sense the gist first, then the kind of thing it was, then the specific episode. HiCM² builds the captioning memory the same way. Training captions are clustered bottom-up into levels, and an LLM summarizes each cluster into one compact sentence, so higher levels hold more abstract knowledge. At inference, retrieval runs top-down: it picks relevant abstract entries first and follows them to finer ones.

On YouCook2 the memory has four levels with 1,758, 313, 68, and 8 entries, built from 10,337 captions. HiCM² reaches 71.84 CIDEr on YouCook2 and 51.29 on ViTT, the best among methods that use pretraining.

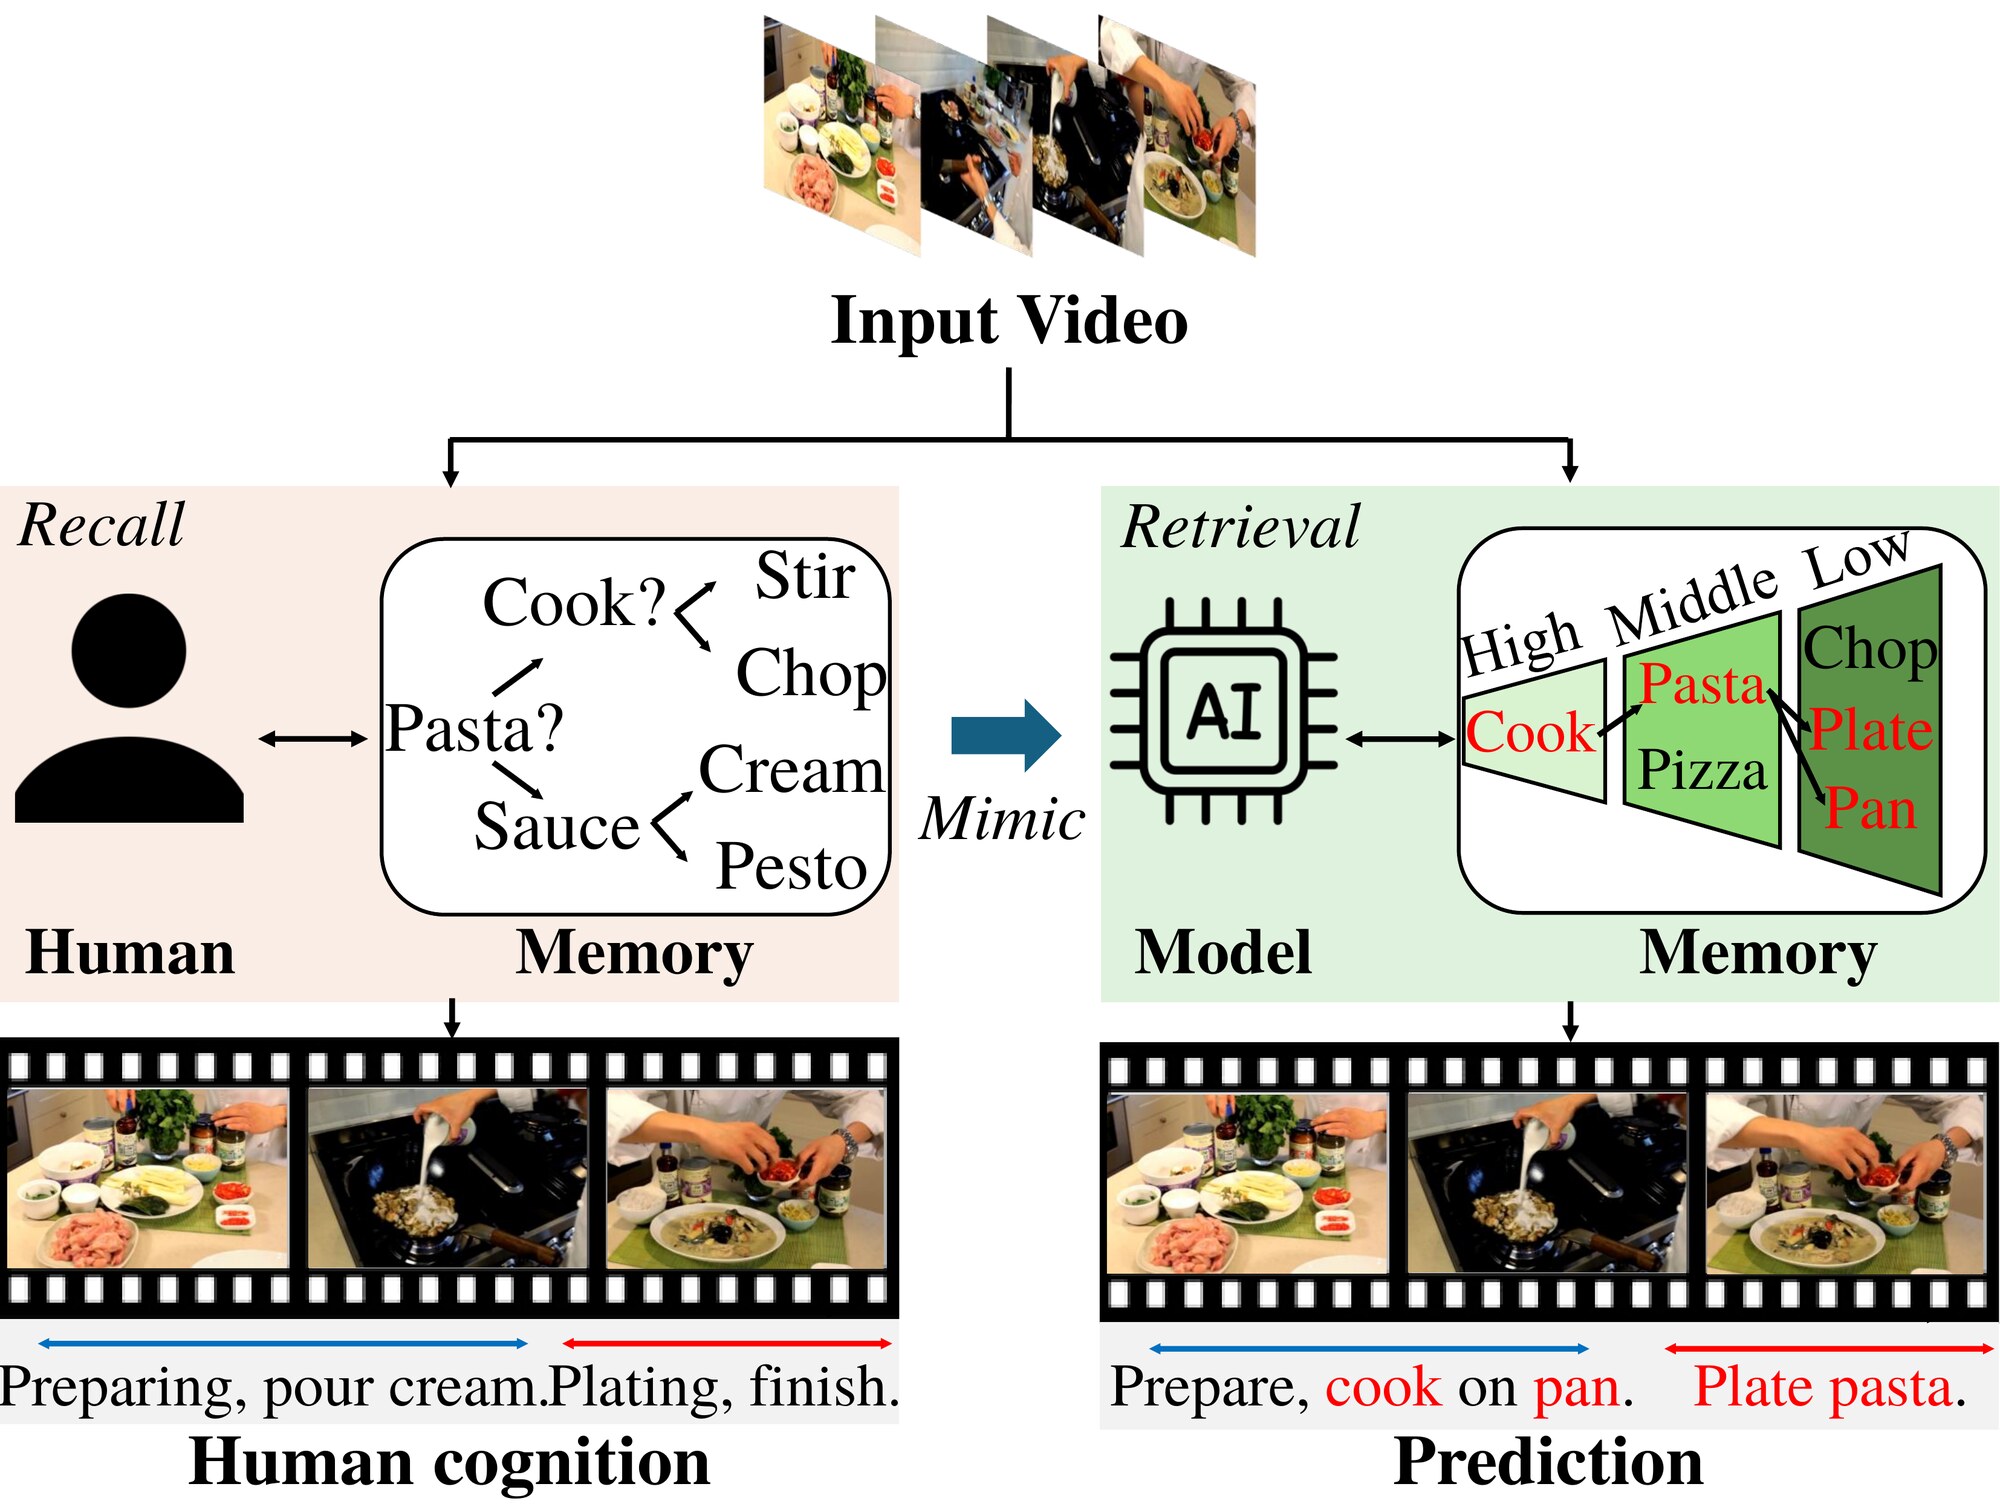
HiCM² concept: humans recall from memory at different levels of abstraction; the model retrieves from a hierarchical compact memory in the same way.
Memory in layers. Like human recall, the model reaches abstract concepts first and specific episodes last.

See it in action

Method

HiCM² overall architecture: video-to-text retrieval at each hierarchical level, a temporal encoder, speech and time tokens, and a text decoder that outputs start time, end time, and caption.
Overall architecture. Retrieval runs at every level of the memory; the retrieved sentences, visual features, and speech are fed to a text decoder that writes each event as start time, end time, and caption.
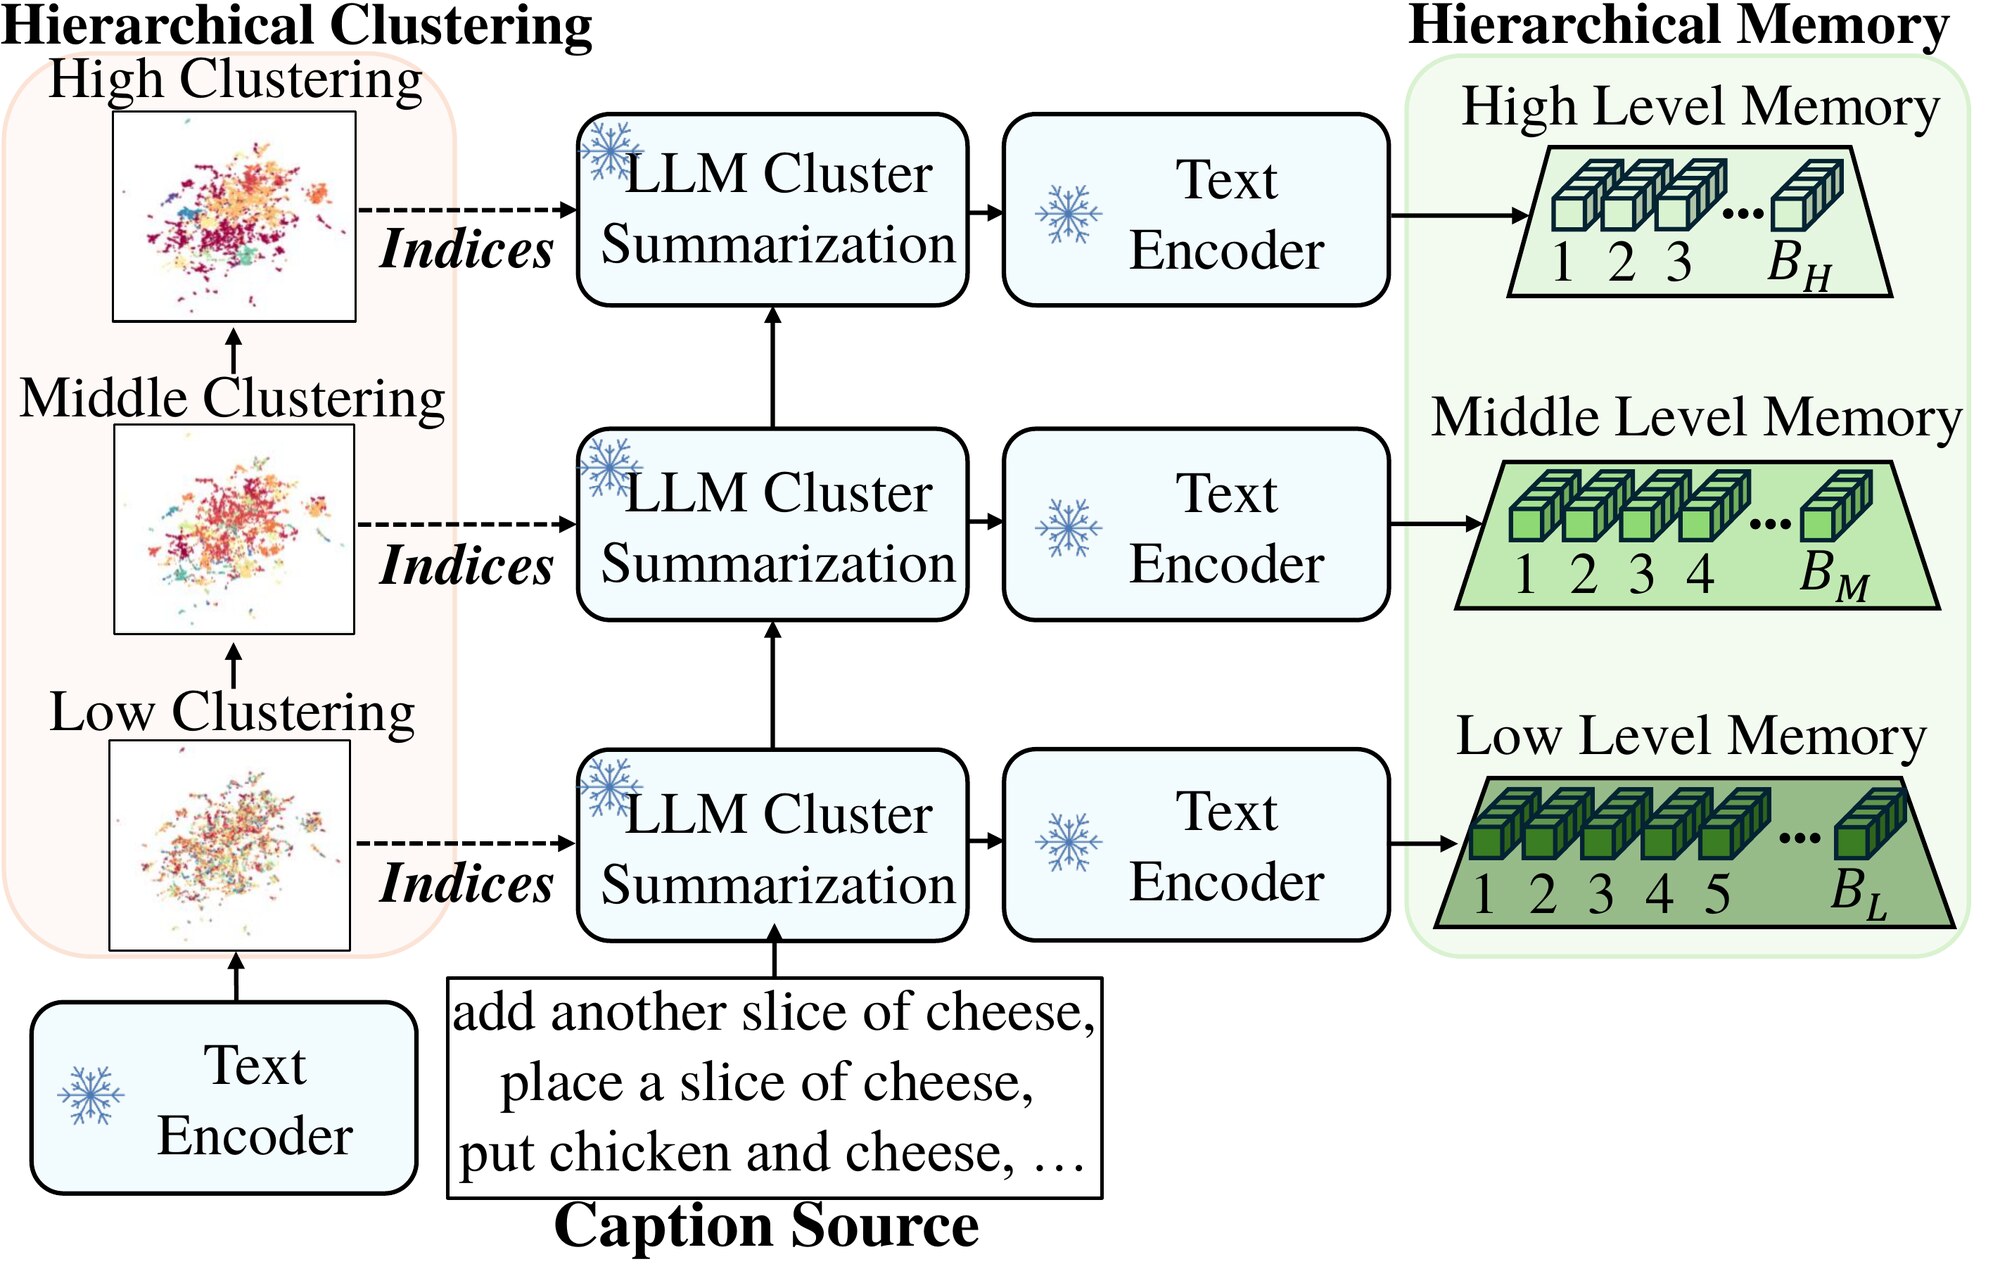
Hierarchical memory construction: captions are clustered at low, middle, and high levels; an LLM summarizes each cluster; a text encoder stores the summaries as memory.
Building the memory, bottom-up. Cluster, summarize each cluster with an LLM, encode, repeat.
Hierarchical memory read: top-k selection at the high level, then hierarchy tracking down to the middle and low levels.
Reading it, top-down. Select at the top, then follow the hierarchy down.

Results

YouCook2 · CIDEr
Vid2Seq† → HiCM²66.29 →71.84+5.55
ViTT · CIDEr
Vid2Seq† → HiCM²48.84 →51.29+2.45

Event captioning

MethodPTYouCook2 (val)ViTT (test)
CIDErMETEORSODA_cBLEU4CIDErMETEORSODA_cBLEU4
PDVC✗29.695.564.921.40––––
CM²✗31.666.085.341.63––––
Streaming V2S✓32.907.106.00–25.25.8010.00–
DIBS✓44.447.516.39–––––
Vid2Seq†✓66.2912.419.875.6448.849.5114.990.71
HiCM² (ours)✓71.8412.8010.736.1151.299.6615.070.86

Event localization

MethodPTYouCook2 (val)ViTT (test)
F1RecallPrecisionF1RecallPrecision
PDVC✗26.8122.8932.37–––
CM²✗28.4324.7633.38–––
Streaming V2S✓24.10––35.40––
DIBS✓31.4326.2439.81–––
Vid2Seq†✓31.0830.3831.8146.2145.8946.53
HiCM² (ours)✓32.5132.5132.5145.9845.0047.00

Bold and underline mark the best and second best, as in the paper. PT: pretraining on additional video datasets. †Reproduced from the official implementation. All methods use a CLIP backbone.

Summaries beat raw captions

A flat memory of all training captions helps a little. Clustering them into a hierarchy is about the same. Writing each cluster as an LLM summary is what lifts CIDEr to 71.84.

MemoryHierarchyCIDErMETEORSODA_cF1
No memory✗66.2912.419.8731.08
All training captions✗67.9012.4910.3832.31
Clustering✓67.1512.9710.1732.30
Clustering + LLM✓71.8412.8010.7332.51
YouCook2.

Every level pulls its weight

Any single level helps over no memory, and using all three gives the best captions (71.84 CIDEr).

HighMidLowCIDErMETEORSODA_cF1
66.2912.419.8731.08
✓67.7512.3310.3532.27
✓67.5912.4510.3732.23
✓67.2112.2110.2831.98
✓✓68.6112.3510.5132.07
✓✓69.8112.6310.5433.00
✓✓68.0512.3310.4132.87
✓✓✓71.8412.8010.7332.51
YouCook2. High is level 4, Mid covers levels 2 and 3, Low is level 1.

BibTeX

CM² · CVPR 2024
@inproceedings{kim2024you,
  title     = {Do You Remember? Dense Video Captioning with
               Cross-Modal Memory Retrieval},
  author    = {Kim, Minkuk and Kim, Hyeon Bae and Moon, Jinyoung
               and Choi, Jinwoo and Kim, Seong Tae},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer
               Vision and Pattern Recognition (CVPR)},
  pages     = {13894--13904},
  year      = {2024}
}
HiCM² · AAAI 2025
@inproceedings{kim2025hicm2,
  title     = {HiCM$^2$: Hierarchical Compact Memory Modeling for
               Dense Video Captioning},
  author    = {Kim, Minkuk and Kim, Hyeon Bae and Moon, Jinyoung
               and Choi, Jinwoo and Kim, Seong Tae},
  booktitle = {Proceedings of the AAAI Conference on Artificial
               Intelligence (AAAI)},
  year      = {2025}
}